Review Only: What Happens When Developers Stop Writing the Code, Part 1
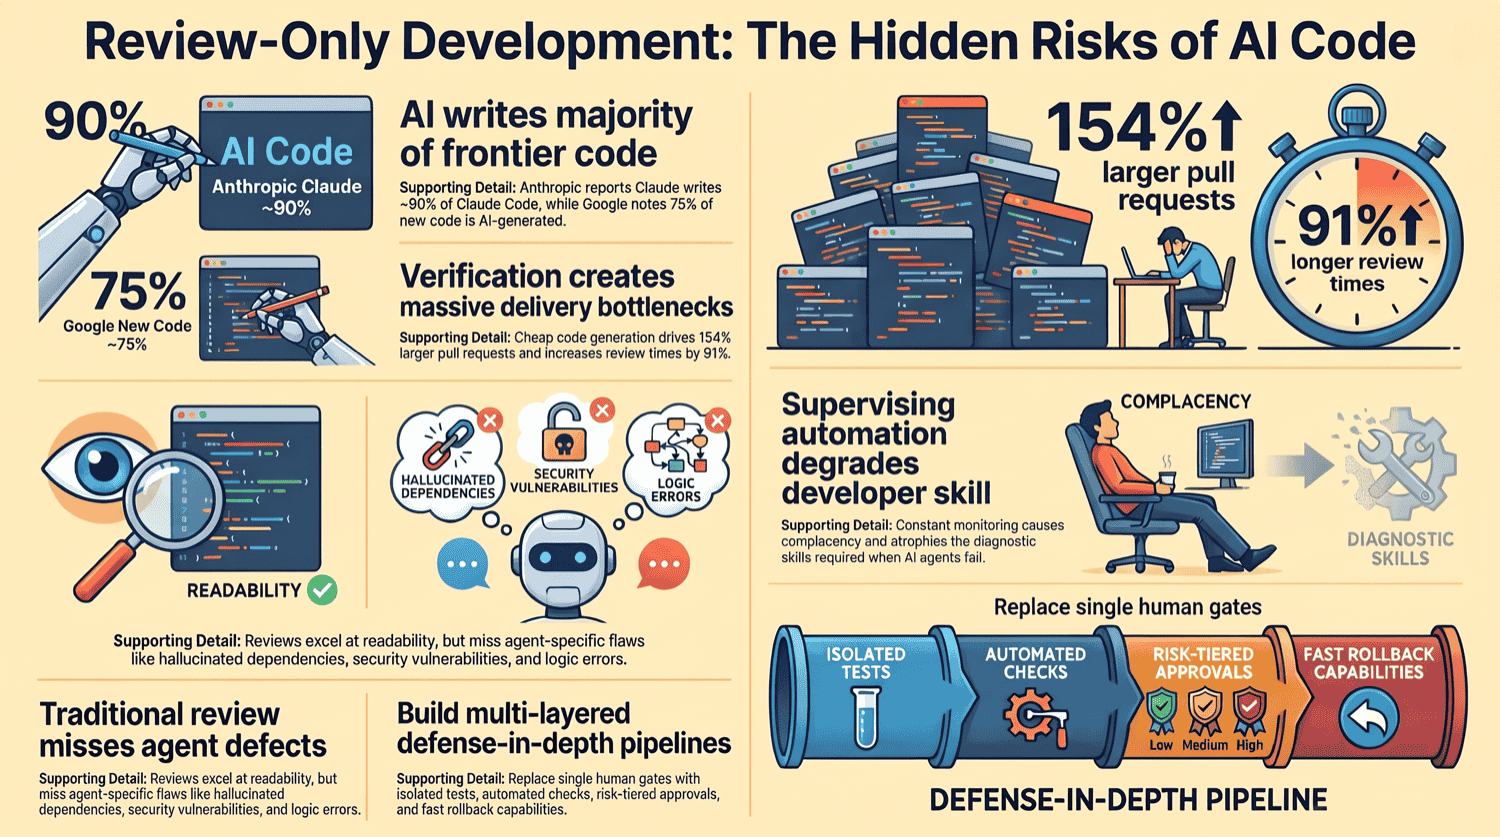
At the frontier of the industry, agents now write most new code and engineers mostly read it. Google says three quarters of its new code is AI-generated, and Anthropic says Claude writes about 90% of Claude Code. As a result, the developer's job is turning into large-scale review of changes they did not write, did not design line by line, and often could not have written as fast. The rest of the industry is following, unevenly.
I look at what the evidence says about that arrangement: (1) how leading teams structure it, (2) whether it is faster end to end, (3) what review catches and what agent code gets wrong, (4) what happens to the people in the loop, and (5) what happens when AI reviews AI. This part covers the first three; Part 2 covers the last two.
In short: (1) the speedup is real at the keyboard and unmeasured end to end, (2) review was never a strong filter for agent defects, (3) the human backstop is losing the practice that made it one, and (4) AI reviewing AI is not an independent check by default.
None of this makes review-only development a mistake. The most careful pipelines I found, Anthropic's layered checks and Meta's risk-gated automatic review, work because they stop treating the reviewer as the last line of defense: they ration human attention by risk, verify the change from outside the agent that wrote it, and make a bad merge cheap to undo. That is where the argument lands: review-only development works when the pipeline is built so it does not need a perfect reviewer, not when one engineer's approval is all that stands between the agent's code and production.
On the afternoon of October 14, 2026, coding agents at Bashi AI, a London fintech startup with a three-person engineering team, finished a front-end restyle and handed it over as a stack of eight pull requests, each built on the branch of the one below. Between 17:05 and 17:15 UTC, one of the team's two software engineers approved all eight, each with a written review of 459 to 870 characters. As it turns out, review agents drafted reviews like these and the engineer checked their findings; the record doesn't show how closely these eight were read.
At 17:16:43 the orchestrating agent ran a single command and merged the seven upper pull requests, top down, in 58 seconds. Each merge changed the code under the next approval, so six of the seven went in on approvals that no longer named the commit being merged, before their tests had even started. The tests began eight to eleven minutes later and passed. Nothing had stopped the merges: branch protection covered only main and production, and each of the seven landed on a branch lower in the stack, where no rule applied. Figure 1 puts the afternoon on one clock.
I take the account from Adam Manji (2026), Bashi's technical lead, who wrote it up himself in a single-company report while preparing for a SOC 2 audit. The merges ran through his GitHub account, so the history shows seven merges by the technical lead. The combined change, 1,325 lines across 56 files, then reached main the proper way: re-approved, tested, merged.
Across his study's enforced period, all 263 merges into main passed the review gate, yet 71 of them, 27%, rested only on an approval an agent had submitted through his account. On paper, each of those merges passed the two-person rule, with one name on the change and another on the approval. But the approval came from an agent, not from the person whose name it carries. In Manji's words, "the record shows a two-person control between two people."
Nothing here shipped a bug, and the gate held everywhere it was installed. One of the engineers summed up their own reading of agent-built changes plainly:
I usually read a good part of the diff, but not every line.— A Bashi AI software engineer, quoted in Manji (2026)
That is what review-only work looks like up close. Every approval is real, and what stands behind it is an open question.
Bashi's engineering team is three people. The companies that set the industry's habits run the same arrangement at a far larger scale: by its own engineering account, Anthropic now merges tens of thousands of code changes a day (Anthropic, 2026).
A more radical version of this arrangement, in which nobody reads the code at all and verification moves to specifications and behavior, is the subject of From Code Complete to Code Missing. StrongDM's AI team has already made it a rule, "Code must not be reviewed by humans," as Simon Willison reported. This post stays with the nearer case, where people still read diffs and sign their names to them.
I set out to find out whether this is safe, and separately whether it is as fast as it looks. The second question turned out less settled than the headlines suggest: in one experiment the tools made developers 56% faster, and in another they made experienced developers 19% slower. The difference between those two settings is most of the answer. The evidence is uneven: some of it is forty years old and solid, some is a vendor's dashboard, and some of the most important studies have not been done. I try to keep the three apart. Figure 2 sums up the argument in one picture; it simplifies, and the caveats are in the text.
01 The Shift to Review-Only Work
Review is old; what the reviewer is reading is new. I start with how a recorded approval became the industry's standard control, then turn to how much of today's code an agent wrote, as each company reports it.
From Inspections to Pull Requests
For most of the profession's history, a code review was a second look, and for much of it not a routine one. Michael Fagan's inspections at IBM in the 1970s made the reading formal: a moderator, a reader, checklists and a meeting, finding errors earlier and more cheaply than testing could (Fagan, 1976). They worked, but they were expensive, and outside safety-critical and defense work most teams did without them.
The lightweight version came from open source and the large web companies. Apache and Linux reviewed patches on mailing lists, before or after they were committed (Rigby et al., 2008); Google made an approving reviewer mandatory for every change (Sadowski et al., 2018); and GitHub's pull request, from 2008, carried the habit to everyone else. By 2013, projects as different as Google, Microsoft, AMD and open-source communities had converged on one practice: small changes, reviewed in a tool by one or two people (Rigby and Bird, 2013). Auditors followed, and a recorded approval became the standard evidence that a change had been controlled.
Through all of it, one assumption held: the reviewer was reading another engineer's work, and every line had passed through a human head at least once. At those organizations, that no longer holds. An agent drafts the change, runs the tests, often reviews its own diff in a fresh context, and opens the pull request; one developer quoted by Baltes et al. (2026) called the reviewer "the first human being to ever lay eyes on this code." In the most aggressive setups, a classifier decides that some changes need no human at all.
Self-Reported Shares of AI-Written Code
Headline numbers come from the companies with the most to gain from them, so for each I give what it says and what it measures.
In April 2026, Sundar Pichai wrote that "75% of all new code at Google is now AI-generated and approved by engineers, up from 50% last fall." I read that sentence in secondary coverage, not in Google's own post. The share was more than 25% on the October 2024 earnings call. It is a share of new code, not of the codebase, and Google has not said how much AI output is rejected or rewritten before it counts.
Anthropic's claim is narrower and more extreme. The Claude Code team's October 2026 post repeats that "Claude writes about 90 percent of Claude Code's own code" (Osmani et al., 2026), which applies to one product repository, not the company. Anthropic's March 2026 product launch adds that code output per engineer "has grown 200% in the last year" (Anthropic, 2026).
Microsoft and Meta have published less. Satya Nadella's on-stage estimate at Meta's LlamaCon in April 2025 was "maybe 20%, 30%" of code in Microsoft repositories, as ITPro reported it. In the same conversation Mark Zuckerberg said he was not sure how much of Meta's code AI was writing and gave a forecast instead: AI would do half of Meta's development within the next year, as Entrepreneur reported. Neither has published a 2026 share-of-code figure; Meta's 2026 account of how it gates review comes in the next section.
Adoption and Trust in the Wider Industry
Outside the frontier, the 2025 picture was different. The Stack Overflow 2025 survey found that 84% of respondents use or plan to use AI tools and 47.1% use them daily, but only 30.9% used agents at work and only 33% trust AI accuracy. Google's DORA 2025 report put adoption at 90% and high trust at 24%. In open source, the AIDev dataset counted more than 456,000 agent pull requests by mid-2025. So review-only work is the norm at AI labs and hyperscalers and a minority practice elsewhere, and no survey I found measures the share of a developer's week spent reviewing rather than writing.
Figure 3 sets the two kinds of number side by side, on separate scales because they count different things. The frontier figures are shares of code, reported by each company about itself; the surveys count developers who use the tools at all, which says nothing about how much of their code the tools write.
Taken together, review is becoming the developer's main contact with the code.
From Vibe Coding to Agentic Engineering
Practitioners have been renaming the practice as fast as they adopt it.
- Vibe coding. Andrej Karpathy's term from February 2025, for accepting AI output without reading it.
- Agentic engineering. The preferred professional term by early 2026: the AI implements, and the human owns quality and correctness.
I have those dates and attributions from secondary write-ups (Turing College, 2026; Ecosistema Startup, 2026). Simon Willison, who defines vibe coding by the absence of review, wrote in May 2026 that the two were "getting closer than I'd like" (Willison, 2026).
The renaming matters because it locates accountability. Every version of "agentic engineering" puts the human's responsibility in the review. Even the most sweeping one does: a position paper that announces "the end of software engineering" still has the human shift from "doing" to "specifying what to do and verifying what was done" (Cao, 2026). The rest of this post, across both parts, asks how much weight review can carry.
02 How the Leading Teams Structure It
The fullest public account of a review-only pipeline is Anthropic's October 2026 post "How the Claude Code team does code review," by Osmani et al. It is a vendor describing its own process, and the vendor sells the AI reviewer at the center of it. It is still the best blueprint anyone has published, and more candid about trade-offs than most.
Human Review as One of Six Layers
Its central choice is to treat human review as one layer among several, not as the gate: six layers of checks, with rollback underneath. The authoring agent verifies its own work and a second agent reviews the diff in a fresh context; parallel AI reviewers propose findings that verifier agents vote on; security review and required CI can each block the merge; human approval is scaled by a risk classifier; and a merge queue, feature flags and a staged release sit over fast detection and rollback.
Human approval is the stage that changes the developer's job. Figure 4 draws the stack and opens up the human-approval layer into its three risk tiers.
Low-risk changes merge with zero human approvals once automated and security review are green. Medium-risk changes, which include ordinary product work and named sensitive areas such as caching, the auto-updater and system prompts, need one person. High-risk changes need two. "The change sets the tier, not the author," the post says, and only trusted authors, mostly the owning team, get the lighter paths. Anthropic's source-control team has since pushed the same idea into the review tool: it "can express complex semantic constraints on approvals, which lets us differentiate simple things like comment-only changes from sensitive logical changes, so that human reviewers can focus on the most consequential changes" (Anthropic, 2026).
Several rules keep a human accountable inside this scheme, and they are the parts other teams tend to skip. "An agent's approval never counts as a person's." Automated review "can clear a low-risk change, but it can't fill a slot that calls for a human." The person directing an agent-written PR counts as a required reviewer. An approval binds to a specific commit, so new commits the system cannot vouch for need a fresh one.
Anthropic's Own Numbers
The stated goal is that most PRs merge "with at most one human in the loop" with "no increase in reverts or incidents." Revert and incident rates are guardrails: if they rise, human time was moved rather than saved. That framing is the part I would most like other organizations to copy.
The reported results are strong. When the AI reviewer launched internally, the share of PRs receiving substantive review comments went from 16% to 54%. PRs passing after one review-and-fix round rose from 65% to 78%, and mean reviews to pass fell from 2.08 to 1.32. The product announcement adds that "on large PRs (over 1,000 lines changed), 84% get findings, averaging 7.5 issues," against 31% and 0.5 issues on PRs under 50 lines; that "engineers largely agree with what it surfaces: less than 1% of findings are marked incorrect"; and that reviews "generally average $15–25, scaling with PR size and complexity."
All of these are Anthropic's internal numbers about Anthropic's product, with no independent check. The under-1% figure counts findings an engineer bothered to mark incorrect, not bugs the reviewer missed; I come back to that gap in Part 2, when AI reviews AI.
Other Companies' Pipelines
Google's published work is older and narrower: in 2023–24 data, code authors addressed 7.5% of all reviewer comments by applying a model-suggested edit (Frömmgen and Kharatyan, 2023). For the 2026 agentic workflow, Google has said only that AI-generated code is "approved by engineers."
Meta has described its own version in a May 2026 preprint by the team that built it (Adams et al., 2026). Its system, RADAR, automatically reviews diffs that a risk model classes as low-risk; it has reviewed more than 535,000 diffs and landed more than 331,000, at a peak of about 25,000 diffs a day. Meta reports that RADAR-reviewed diffs have a third of the revert rate and a fiftieth of the production-incident rate of other diffs, which mostly reflects which diffs it is allowed to touch. The direction is Anthropic's: automate the low-risk tier and save people for what the risk model escalates.
Stripe and Uber describe parts of the same pattern on their own engineering blogs. Stripe says over a thousand merged PRs a week "are completely minion-produced" and, "while they're human-reviewed, they contain no human-written code" (Gray, 2026). Uber's uReview, an AI second reviewer, covers more than 90% of about 65,000 diffs a week, and Uber reports that developers address more than 65% of its comments against 51% of human ones (Mahajan et al., 2025). Neither has an outside check.
Shopify's published gate is the stricter shape: agents work in drafts, a freshness-gated merge queue holds the merge, and human merge authority is written in code rather than in a prompt, which took security remediation through that queue from about 10% to 80% (Son and Li, 2026).
03 Is It Faster from Idea to Production?
The reason most often given for review-only work is speed, and the claim needs care about which speed is meant. Writing code faster is one thing; getting a change from an idea to something running correctly in production, through review, rework and queues, is another. The evidence on the first is plentiful.
On the second, there is almost none.
The theory of constraints has a blunt lesson here: a pipeline's throughput is set by its slowest stage, and speeding up any other stage just builds inventory in front of the bottleneck.
When generation becomes nearly free, the slow stages are the ones on either side of it: specification, deciding precisely what to build, and verification, checking that it was built right.
If agents open PRs faster than reviewers clear them, work in progress and lead time grow even though each change was written in minutes.
Armin Ronacher, the creator of Flask, says the same from the maintainer's chair: "Historically, writing code was slower than reviewing code" (Ronacher, 2026).
Experiments Measure Tasks and PRs, Not Lead Time
METR's randomized trial from early 2025 is still the cleanest experiment on individual speed: sixteen experienced open-source developers, 246 real issues in repositories they knew well. With AI allowed, tasks took 19% longer (confidence interval +2% to +39%), though the developers had forecast a 24% speedup and afterwards still believed in a 20% one.
METR's February 2026 update estimates that late-2025 tools cut task time, by 18% for returning developers and 4% for new recruits; its figure is captioned "Late-2025 AI likely accelerated open-source developers," which settles the sign. Both confidence intervals cross zero, and METR calls the estimate "likely a bad proxy" because developers increasingly refused to work without AI.
Larger field experiments measure output, not time. Randomized Copilot rollouts at Microsoft, Accenture and a third company, pooled over 4,867 developers, raised pull requests by about 26% while build success fell, significantly so at Accenture (Cui et al., 2026). A Google RCT of 96 engineers found about 21% less time on one task (Paradis et al., 2024), and in Microsoft's 2026 rollout of Claude Code and Copilot CLI adopters merged about 24% more PRs, though "a merged PR is not the same as the value it delivers" (Murphy-Hill et al., 2026).
None of these measures lead time.
Review Is the Constraint
If review is the constraint, an organization has three moves. It can add review capacity, which is what an AI reviewer is; it can lower the bar per change, which is what risk tiers do; or it can let the queue grow. The third happens by default.
Two recent papers make the mechanism concrete. A single-author simulation of DevOps teams (Alenezi, 2026) found that AI-generated code shortened lead time only "where review capacity was spare," by 13%, and "lengthened it once review saturated." In a 15-day industrial case study in a large C++ repository (Bexell et al., 2026), hundreds of AI-generated commits saturated both CI and reviewer attention until the team batched changes by directory and capped the files per change: "When mechanical editing is cheap, CI capacity, review effort, and change orchestration become primary bottlenecks."
Figure 5 redraws the simulation's lead-time results for code generation alone:
- Spare review capacity. The team gets steadily faster as the AI share rises.
- No spare capacity. Lead time is flat to the halfway mark and up 10% at three quarters.
- No spare capacity, all code AI-generated. Mean review wait goes from 2.8 hours to 72 hours, and lead time rises 420%.
Measured data from one company fits the mechanism. A paper by He et al. (2026a) follows a mid-sized, "AI-forward" software company, unnamed in the paper, whose CTO set a goal in June 2025 of doubling merged pull requests per engineer with AI. Over 802 developers and 196,212 pull requests, AI-authored changes reached about 90% of output and PR volume rose 3.1-fold against a reviewer pool that grew 1.5-fold, from 21.2 pull requests per active developer per month to 44.3. Over the same period the share of merged PRs that got substantive human review fell from 48% to 21%, and the 90th percentile of commit-to-merge peaked near 66 hours. Reverts and post-merge fixes stayed flat.
The queue never decongests; the aggregate improves by routing work around it.
Anthropic's own numbers are absolute, and steeper. It merged about 2,500 code changes a day in May 2026 and more than 30,000 a day by September, a twelvefold rise in five months, and its source-control team describes the result as a change of bottleneck: coding stopped being the constraint, and "source control, builds, and CI" became one (Anthropic, 2026). Figure 6 puts the two published points on one axis.
At that rate the merge queue stops working as a queue.
Merge Queues Weren't Built for Agent Scale
Anthropic now argues that "a proper merge queue doesn't make much sense at agent scale," asking what CI means when thousands of changes can merge while tests run, and has put its effort into post-merge and pre-deploy testing instead, accepting that concurrent changes sometimes conflict and that Claude usually fixes a conflict faster than a person could find it (Anthropic, 2026).
For scale, GitHub merged 1.3 billion pull requests in the twelve months to September 2026, an average of 3.5 million a day across public and private repositories (GitHub, 2026). How much of that is agents depends on who counts. An independent mining of public GitHub events attributes 12.5% of new public pull requests that September to Claude or Codex branches, roughly 77,000 a day between the two (vester.si, 2026). The counting is messy: it misses agents opened under a person's own account and counts a human branch named claude/.
Agent-scale development moves the bottleneck into the plumbing, and not only inside Anthropic. GitHub has had several significant outages since agents began landing code at this rate, including one in August that ran nearly eight hours, and is moving the platform onto Azure for capacity. Cursor shipped its own code-hosting service in August. Entire, a startup led by GitHub's former chief executive, launched a forge built for teams "whose AI agents write code faster than people can review it", replacing the pull request with a dashboard of scores from reviewing agents and claiming 89 times GitHub's push throughput on its own benchmarks.
None of that shows review getting better. It shows that the layer built for human-scale merging is the one that breaks first, and that vendors now sell against that failure.
AI Review Can Shorten Cycle Time or Lengthen It
Field studies of AI reviewers point both ways. At Atlassian, a year-long evaluation of the RovoDev reviewer found PR cycle time down 30.8%; at an unnamed company using a Qodo PR-Agent-based reviewer, average PR closure time rose from 5h52m to 8h20m (Cihan et al., 2025). An AI reviewer can clear the queue or lengthen it, depending on how much noise it adds.
Anthropic's account is the strongest positive case. "From June to September, merged pull requests to Claude Code's codebase more than doubled while the share that had to be reverted fell by more than 40 percent" (Osmani et al., 2026). Those are the numbers a review-only skeptic has to answer, and the honest answer is that they are one vendor's own, measured on its own product, with the AI reviewer it sells.
The only before-and-after numbers on dropping human review for low-risk changes come secondhand, through Gergely Orosz's newsletter. Duckbill Group, a five-person team, went from 353 to 684 merged PRs, with a median merge time of 26 hours for human-reviewed PRs against one hour for the rest. That measures the wait removed, not what the skipped reviews would have caught.
Speed at review can also mean the review did not happen. Siddiq et al. (2026) found that non-security agent PRs in open source closed in a median of 0.11 hours, about seven minutes, far outside the regime in which review has been shown to work. Across about 110,000 agent PRs, Popescu et al. (2026) found the median Codex PR merged in half a minute, which the authors attribute to rote changes or review done before the PR was opened. Neither is faster review.
Telemetry: More Code, Slower Review, Less Stability
The best-known telemetry study in this area is Faros AI's July 2025 "AI Productivity Paradox" report, covering more than 10,000 developers in 1,255 teams. Faros sells engineering analytics and the results are correlational. Figure 7 plots the deltas for high-adoption teams as given in its key-findings post.
The developers completed 21% more tasks and merged 98% more PRs; their PRs were 154% larger and took 91% longer to review, and bugs per developer rose 9%. Yet Faros found no significant link between AI adoption and company-level throughput, DORA metrics or quality, or as its report page puts it, "company metrics remain flat." That is what a constraint looks like from the outside: more inventory, a longer queue at the bottleneck, and no change in what leaves the factory.
Faros AI's 2026 follow-up, from 22,000 developers in 4,000 teams, shows on its own report page, which I did not open in full, median review time up fivefold and incidents per PR up threefold. A widely repeated 31% figure for PRs merged without review is not there, so I leave it out.
DORA's 2025 survey finds AI adoption now positively associated with delivery throughput, reversing the 2024 finding, while it "does continue to have a negative relationship with software delivery stability." Throughput up and stability down is the signature of a pipeline that ships faster and pays for it after the merge.
Meta's RADAR paper gives the most direct industrial picture of the gap. Significant lines of code per human-landed diff, a filtered measure Meta defines itself, grew 105.9% year over year and diffs per developer 51%, with "agentic AI responsible for over 80% of that growth," while "the share of diffs receiving timely review has declined." Figure 8 redraws Meta's chart; the paper gives no values for the timely-review series, so I show only its direction.
Late Rework and Rising Complexity
Some of the speed comes from patches that look finished. Re-examining SWE-bench Verified, Wang et al. (2026) found that 7.8% of patches counted as correct fail the developers' full test suite and that 29.6% of plausible patches diverge from the reference behavior, inflating reported resolution rates by 6.4 points. A patch like that passes review and CI, merges fast, and returns as a bug report weeks later; time-to-merge books it as a win.
Benchmarks that chain tasks instead of grading them one at a time show the same drift. On SWE-Milestone (first released as EvoClaw), which replays development milestones reconstructed from real commit histories, 12 frontier models across four agent frameworks scored above 80% on isolated tasks and 38.03% when each task built on the last (Deng et al., 2026). A reviewer reading one diff at a time sees only the isolated task.
Mining studies of what happens after the merge point the same way, with small effects. A preprint following 6,774 merged agent PRs (Takerngsaksiri et al., 2026) reports, from its abstract, follow-up fixes at 1.62 times the odds of human PRs, while revert rates vary by agent: a single-author preprint (Kraishan, 2026) reports Codex PRs reverted less often than human ones (6.1% against 11.5%) and Devin's more often (14.5%).
The causal studies on GitHub agree on a pattern I find more telling. Comparing Cursor adopters with matched controls, He et al. (2026b) found a "large, but transient" velocity gain and a "substantial and persistent" rise in static-analysis warnings and code complexity, which then drove a slowdown. For agent adoption, Agarwal et al. (2026) report warnings up about 18% and cognitive complexity about 39%, and a stricter design puts the complexity rise nearer 11% in Python (Xu et al., 2026). The direction holds; the size does not.
One RCT points the other way. In Borg et al. (2026), developers evolving AI-assisted code without AI took no longer and did no worse than those evolving human-written code, the only direct measure of downstream maintenance cost I found.
Single-company reports show how slippery throughput becomes once agents run the pipeline. In two industrial "software factories" (Jiang and Lysenko, 2026), daily merges rose fifteenfold during the agent rollout, and at least 5.6% of issues marked fixed had incorrect fixes.
I found no study that measures end-to-end lead time, from idea to a change running correctly in production, for review-only teams against comparable teams. The closest thing is a customer story from the vendor side: Coinbase reports idea-to-production falling from 20 days to 1.8 with Cursor, no control group and no published method, which is the number a skeptic will cite and the one I cannot check.
Everything above measures one segment; the nearest with a method are Meta's share of diffs reviewed within a day, a Jellyfish analysis (Chretien and Albarran, 2024) that found Copilot users' cycle time down 8% in the completion era, and a simulation.
Over longer windows the picture is mixed. In six large open-source projects, Ebiwonjumi et al. (2026) found time to merge unchanged between 2018–2021 and 2022 onward, while review comments per PR fell from 3.12 to 2.47 and PRs merged with no comment rose from 62.9% to 69.1%; the study does not measure AI use per PR. A workshop preprint following 400 repeat reviewers of agent PRs for seven months (Yu et al., 2026) reports, in its abstract, review latency up 3.5-fold, inline comments down 22% and approvals up, which the authors call "reflexive habituation under growing workload."
So, Is It Faster?
For writing the code, mostly yes. Past that point, the answer depends on what kind of work is being measured, and the studies above measure very different kinds. Figure 9 lays the evidence out along the path from idea to production: each stage has been measured on its own, and no study joins them up.
The largest speedups come from greenfield work. In an early Copilot experiment, developers asked to build an HTTP server in JavaScript, with no existing code to fit into, finished 55.8% faster with the tool (Peng et al., 2023). METR's trial is the opposite setting: mature projects with high quality standards, and developers with an average of five years on the code they were changing. There, AI made them 19% slower. The field experiments sit in between, and in them the gains went to recent hires and junior developers, not to those with long tenure (Cui et al., 2026). The less code there is, and the less the developer already knows it, the more the tool helps. Most production work is the reverse: changes to a large system that someone has to keep running.
Time changes the answer too. A task measured on its own looks better than the same task in a codebase that keeps moving: agents that cleared 80% of isolated tasks on SWE-Milestone managed 38% when each task built on the last, and Cursor adopters' velocity gain faded while the complexity it left behind did not. Borg et al.'s maintenance experiment suggests that cost may be smaller than it looks, but it lands after the speed has been booked.
Then there is the pipeline. Where review has spare capacity, faster generation shortens lead time; where it does not, the queue absorbs the gain or reverses it. The teams that report more merges without more reverts rebuilt their review stacks to get there, so where it is faster end to end, the pipeline made it faster, not the agent alone.
So for production-quality output, the jury is probably still out. Prototypes, greenfield code and rote changes are clearly faster to produce. Changes to a mature system that still work months after the merge, which is where most engineering time goes, have not been shown to be faster, and the measurement that would show it, from idea to a change running correctly in production, has not been taken.
When writing code gets cheap, specification and verification set the pace, and the stages after the keyboard are where the gain goes. A faster queue is only worth having if review still catches what matters, and that is the next question.
04 The Defects Review Was Never Built to Catch
A review-only workflow bets that human review is a good filter for the defects agents introduce. What review has been measured to catch and what agent code has been measured to get wrong do not fit well together.
Even Good Review Catches About Half the Bugs, Mostly Maintainability
The sharpest modern number on how much review catches is a measurement, not a guideline. A 2026 benchmark traces 1,000 review tasks across 98 repositories back to the pull request that introduced each bug, and finds human review catching half: 49.7% before the merge and 50.3% only after it. The best AI reviewer in the same study caught 71.9% within its top five comments, against 47.7% five months earlier, and the two together 82.1% (Yang et al., 2026).
That 50% is recall measured on bugs that mattered later, so it is a floor on review's miss rate rather than a general detection rate; the same study finds larger diffs markedly harder to review, at an odds ratio of 0.591. Apart from this benchmark, I found no modern field estimate of how many defects lightweight review catches.
Peer-reviewed work says that even good review mostly finds a different kind of problem. Mäntylä and Lassenius (2009) found that 75% of defects found in industrial and student reviews do not affect visible functionality; they are evolvability issues such as structure, naming and documentation.
Bacchelli and Bird (2013), at Microsoft, found that developers review mainly to find defects, but that reviews mostly deliver code improvement, knowledge transfer and team awareness, and that understanding the change is the hardest part.
Microsoft's "Code Reviews Do Not Find Bugs" (Czerwonka et al., 2015) reports, in the authors' summary material, that only about 15% of review comments indicate a possible defect, a share of comments rather than a detection rate; at least half concern long-term maintainability. Usefulness, as judged by the change's author, falls as reviews grow, noticeably from about 20 changed files.
Review Works Best on Small, Familiar Diffs
The best-known numbers on review size and speed come from a SmartBear study of 2,500 reviews at Cisco (Cohen, 2006). Defect-finding density drops sharply beyond about 200 lines and is "almost zero" after 400, and SmartBear advises reviewing fewer than 200–400 lines at a time at "less than 300–500 LOC/hour." The study was run by the company selling the review tool and never peer reviewed, so I treat it as a strong heuristic, not a measurement.
At Google, Sadowski et al. (2018) describe, in the summaries I could check, a median change of about 24 lines with a single approver, a regime of small diffs that review handles well.
Familiarity matters as much as size. Across 1.5 million review comments in five Microsoft projects, Bosu et al. (2015) found that reviewers who had reviewed a file before had 65–71% of their comments judged useful, against 32–37% for first-time reviewers, and that usefulness kept rising up to about five prior reviews of the file. In review-only work, every agent PR is code the reviewer has never seen in draft.
Review does improve quality when people actually do it. Components of Qt, VTK and ITK with low review coverage carried up to two extra post-release defects, and those with low participation up to five (McIntosh et al., 2014); at Sony Mobile, context-specific review measures predicted defects where generic coverage did not (Shimagaki et al., 2016). The effect depends on participation and expertise, both of which degrade when reviewers are flooded.
Generated Code Is Less Secure and Harder to Maintain
Those are the conditions review was measured to need. The code agent PRs carry has weaknesses of its own. The security evidence on generated code is the oldest and most consistent. Pearce et al. (2022) found about 40% of the 1,689 programs Copilot wrote for 89 scenarios built around MITRE's Top-25 weaknesses to be vulnerable. That was 2021's Copilot, and the studies below show the problem has not gone away.
The more important study for this post is about people. In Perry et al. (2023), participants with an AI assistant wrote less secure code than a control group on most tasks: on encryption, 21% secure answers against 43%. They were also more likely to believe their insecure code was secure. The pooled effect narrowly missed significance (p = 0.056), while several per-task effects were significant, and participants who trusted the AI less wrote more secure code. A reviewer-only safeguard inherits exactly that miscalibrated confidence.
Veracode's 2025 report, from a vendor that sells application security scanning, tested more than 100 models on 80 curated tasks and found that code which worked introduced a vulnerability in 45% of cases, with Java worst at 72%.
A related class of defect is nearly invisible in a diff. Spracklen et al. (2025) analyzed about 2.23 million package references from 16 models and found that 19.7% pointed to packages that do not exist, and that 43% of the invented names reappeared in all ten re-runs of a prompt, which makes them registrable by an attacker: the attack now called slopsquatting. A plausible package name looks fine in a diff; the risk lives in the registry, where the reviewer is not looking.
Two vendor reports cover maintainability, and both have obvious interests. CodeRabbit, which sells an AI reviewer, reported about 1.7 times as many issues per AI-co-authored PR as per human-only PR in 470 open-source PRs, as classified by its own AI reviewer (CodeRabbit, 2025). GitClear, which sells code analytics, found moved lines, a sign of refactoring, falling from 24.8% of changed lines in 2021 to 9.5% in 2024 while copy-pasted lines rose from 8.4% to 12.3% (GitClear, 2025, figures as reported by LeadDev), without attributing lines to AI. Duplication is the defect review is best at catching, and it rose anyway: it builds up across many PRs, and each review sees one.
Tests Pass, but the Patch Does Something Else
Vulnerabilities, invented packages and duplication can at least be scanned for. A harder class passes every automated check. In the SWE-bench re-examination discussed earlier, the divergent-but-plausible patches were mostly "similar but divergent implementations" (46.8%) or patches that changed more behavior than the reference fix (27.3%). Both pass the tests, read cleanly, and look like a competent colleague's work, which is what makes them hard to review. Figure 10 shows how far three agents' reported resolution rates fall under stricter checks, and what manual inspection made of 77 divergent patches.
An empirical taxonomy of bugs in LLM-generated code (Tambon et al., 2024) maps the same territory: misinterpreted intent, missing corner cases, hallucinated objects, wrong attributes, and "non-prompted considerations," behavior nobody asked for.
Two Kinds of Study, One Direction
The evidence above comes from studies of very different kinds, and it is worth separating them. Figure 11 sorts the defect findings by source, so the weight of each line is visible.
| Source | Kind of evidence | Finding | Caveat |
|---|
| Academic studies | |||
|---|---|---|---|
| Pearce et al. 2022 | Controlled benchmark | About 40% of 1,689 Copilot programs vulnerable | 2021 model |
| Perry et al. 2023 | User study, 47 people | AI users wrote less secure code and rated it more secure | Pooled p = 0.056 |
| Spracklen et al. 2025 | Large-scale measurement | 19.7% of package references invented; 43% repeat every run | Per-model figures vary |
| Wang, Pradel, Liu 2026 | Re-analysis of SWE-bench | 29.6% of plausible patches diverge; rates inflated 6.4 points | Python benchmark repos |
| Vendor reports | |||
|---|---|---|---|
| Veracode 2025 | Vendor benchmark | 45% of working solutions introduced a vulnerability | Sells AppSec scanning |
| CodeRabbit 2025 | Vendor comparison | About 1.7x issues per AI PR | Own AI classifier; 470 PRs |
| GitClear 2025 | Vendor telemetry | Moved lines 24.8% to 9.5%; copy-paste 8.4% to 12.3% | No line-level AI attribution |
The academic rows and the vendor rows agree in direction, which is worth something: the vendors have an interest in AI code looking risky, but the controlled studies have no such interest and found the same thing first.
Agent Output Arrives Large and Unfamiliar
The conditions under which review was shown to work are close to the opposite of what agent output produces. Figure 12 sets them side by side.
| Factor | Where review was shown to work | What agent PRs look like |
|---|---|---|
| Change size | Under 200–400 lines per sitting (SmartBear); Google median about 24 lines | PR size up 154% in high-adoption teams (Faros AI, 2025); all "too large" rejections in one study were agent PRs |
| Pace | Under 300–500 lines per hour (SmartBear) | Median about 7 minutes to close a non-security agent PR in open source |
| Familiarity | Reviewer knows the code; useful comments nearly double after a first review of a file (Bosu et al.) | The reviewer's first contact with the code is the review |
| Load | Participation and expertise drive the quality effect (McIntosh) | Merged PRs up 98% in high-adoption teams, with review time up 91% (Faros AI, 2025) |
| Defect type | About 75% of findings are evolvability issues (Mäntylä) | Intent errors, missing corner cases, insecure defaults, invented dependencies |
Developers describe the same conditions. In interviews at the automotive software company WirelessCar (Aðalsteinsson et al., 2025), one said of a large change that "people don't dare to pick it up," and others described large mixed PRs leading to "more superficial reviews." Each row of the table is a separate study, but every row points the same way: large diffs, in volume, reviewed fast, in code nobody on the team has held in their head.
The size row holds within a single sample. Across about 110,000 open-source PRs, Popescu et al. found that the median Claude Code PR changed 376 lines against 60 for a human one (a modified line counts twice), while Codex's median was about the human size.
Figure 13 sets those medians against the SmartBear range, the shaded band from the Cisco study's advice to review under 200–400 lines per sitting. That is a vendor's guideline, from a different study and a different unit, not a limit on one PR, but Claude Code's and Copilot's medians already fall inside it.
Reviewers Distrust Agent PRs but Rarely Say Why
The 2026 mining studies show how agent PRs carrying these defects meet reviewers. In repositories with at least 100 stars, Nakashima et al. (2026) found acceptance rates of 85.8% for Codex, 71.3% for Claude Code and about 55% for Devin and Copilot, against 82.6% for humans. In a sample of 654 rejected PRs, 67.9% were closed with no reviewer feedback at all, and seven rejection categories, including "No confidence in AI-generated code," appeared only for agent PRs.
Of 33,596 curated agent PRs studied by Siddiq et al., 3.85% were security-related; those merged less often (61.5% against 77.3%) and waited far longer for review, which measures perceived risk, not whether the merged code is secure. Two further preprints report that 38.9% of agent PRs contain at least one security smell (Sakib et al., 2026) and that agent dependency changes slightly increase net vulnerabilities (Singla et al., 2026); I saw both only through search snippets.
Why AI Bugs May Be Harder to Review
Here I am inferring, not reporting.
Human bugs often come with visible signs of struggle: awkward structure, a TODO, a function that grew three special cases. Those signs draw a reviewer's eye. Agent bugs arrive in clean, confident, well-formatted code that passes its tests. The defect classes agents are known for are the ones review is weakest at catching, and the ones review is best at catching, such as duplication, build up across many PRs where no single review sees them.
Nobody has tested this directly. No controlled experiment seeds AI-made and human-made bugs into otherwise similar changes and measures how often reviewers catch each, and I return to it under Open Questions in Part 2.
Human review was measured to work on small, familiar diffs read slowly, and agent output is the opposite on every count. Figure 14 sets what review catches against what agents hand it, defect by defect.
The defects agents are known for are the ones review has always been weakest at, and nobody has yet measured whether reviewers catch AI-made bugs as often as human ones.
This is Part 1 of a two-part post. It covers how review-only work spread, how the leading teams structure it, whether it is faster from idea to production, and what review catches against what agent code gets wrong.
Part 2 turns to the human in the loop, AI reviewing AI, who answers when reviewed agent code fails, and what to build and test in the meantime. All references for both parts are in Part 2.