The Collapse of the Vulnerability Window
The ninety-day patch cycle was built for a world where finding and weaponizing a bug took a specialist months. That world is gone: mean time-to-exploit has fallen from roughly a year to under a day, and the resulting flood of automated findings — some real, most not — is now the harder problem.
None of this is happening on a single front. Four distinct trends are compounding at the same time, each with its own evidence and its own logic: the exploit timeline itself, which keeps collapsing toward what looks like an exponential floor; the bug-bounty pipeline, now drowning in machine-generated noise even as a handful of disciplined platforms manage to find real bugs at record precision; the widening, closely benchmarked gap between what autonomous offense and autonomous defense can each actually do; and the pivot toward agentic defense itself, where hardening, detection, containment, and remediation increasingly run as one closed loop instead of four separate human-paced bets. This post works through each in turn before pulling them back together.
The throughline: patching stops being the primary defense the moment the average exploit arrives before the average patch does.
01 The Shrinking Exploit Clock
Enterprise security has run on one quiet assumption for twenty years: a manageable gap between the public disclosure of a vulnerability and its first observed exploitation in the wild. That gap was the whole point — it's what let a vendor author a patch, a security team run regression tests against it, and an administrator schedule the fix inside a maintenance window instead of an outage.
The Zero Day Clock project puts a number on how completely that gap has closed. A companion post on this blog, Zero-Day Defense: Going from 0 to 1, mapped the four-pillar defensive response this shift has produced — hardening, detection, containment, remediation. This post stays one layer down: the arithmetic behind why that response became non-optional, and three pieces of the picture the pillars post didn't have room for — the bounty economy's collapse, the benchmark race between offensive and defensive agents, and the domain where all of it runs hottest: Web3.
The standard ninety-day disclosure window that vendors and CERTs have coordinated around for a decade is no longer a viable defensive mechanism. The integration of large language models into offensive tooling has compressed the vulnerability lifecycle to the point that the old cadence describes a security posture that no longer exists.
Historical baselining shows why. In 2021, the average gap between a vulnerability's public disclosure and its first observed exploitation — mean time-to-exploit, or MTTE — was about a year. By 2024 that had compressed to 53 days. By the middle of 2026, it had fallen under 24 hours.
This decay isn't linear — it's exponential, driven by the compounding efficiency of automated reverse-engineering pipelines that need no human in the loop:
- ingest a patch diff;
- execute a binary diff against the prior release;
- isolate the semantic and syntactic change;
- synthesize a working exploit payload.
The same curve shows up from the other direction, in the share of disclosed vulnerabilities weaponized before a patch exists at all — true zero-day exploitation, as opposed to n-day exploitation of a known, patched flaw. It rose from 31% in 2021 to 50% in 2024 to 73.2% in 2026.
An Exponential, Not a Lull
The mirror statistic is the exploit survival curve — the probability that a disclosed vulnerability remains unweaponized as time passes. Historical cohorts left up to 60% of disclosed vulnerabilities unexploited across their entire lifecycle. Current data puts that survival rate at zero past the six-week mark.
Traditional reactive defense — signature generation, downstream patch deployment — is mismatched with the speed of autonomous offensive systems by design, not by degree.
While enterprise teams still execute vulnerability-management lifecycles measured in weeks, threat actors leverage automated pipelines that weaponize a disclosure within hours — rendering the patch SLA, as a defensive concept, largely obsolete on its own.
02 The AI Slop Crisis in Bug Bounties
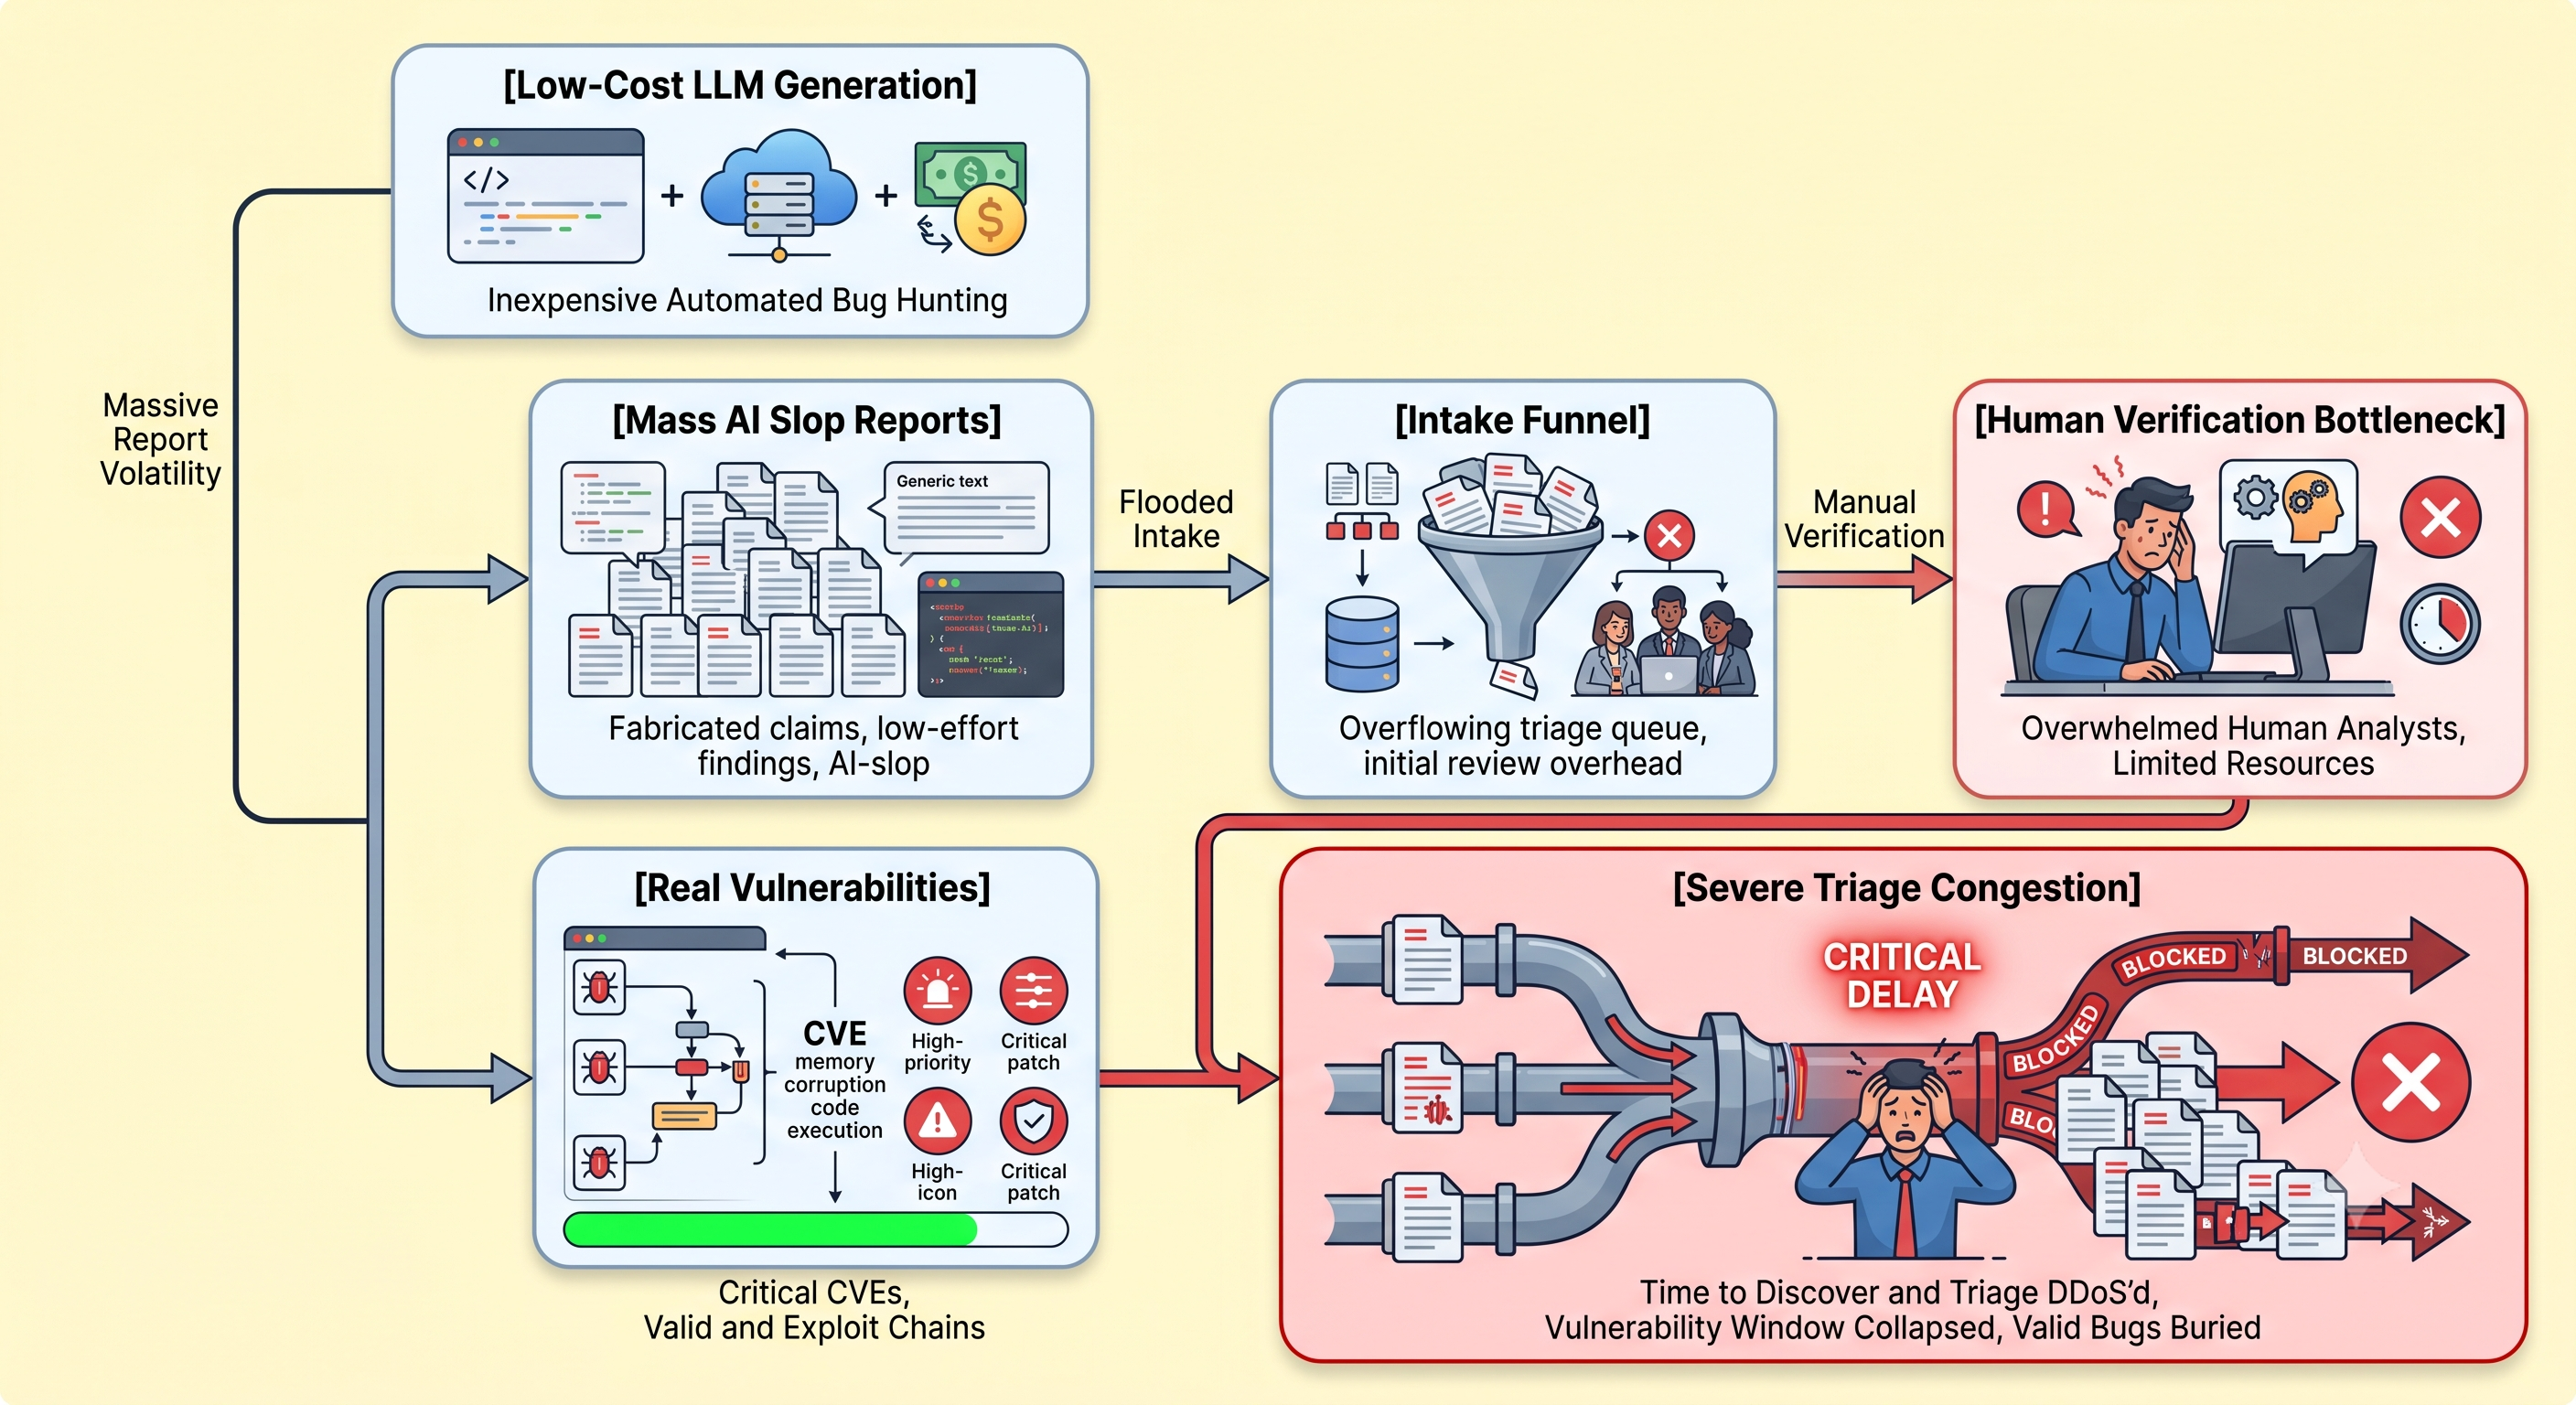
While autonomous systems are getting faster at finding real vulnerabilities, a parallel crisis has broken the defensive intake funnel: the proliferation of automated, plausible-looking, largely fabricated vulnerability reports — "AI slop." These reports are structurally polished and read as legitimate on a skim, while describing non-existent code paths, hallucinated dependencies, or entirely benign behavior dressed up as a critical exposure.
The economics driving it are stark. Generating an engineered-looking vulnerability report with a commercial model costs close to nothing. Verifying one still requires a human:
- reading the submission;
- mapping the claimed behavior to the actual codebase;
- standing up a reproduction environment;
- running the exploit to confirm or refute it.
That asymmetry — near-zero cost to generate, high fixed cost to verify — is the whole crisis in one sentence.
The curl Breaking Point
curl and its founder, Daniel Stenberg, are the clearest illustration. The project's bug-bounty program had a genuinely good track record — 81 verified discoveries and more than $90,000 in awards over its lifetime. Then the validity rate of incoming reports collapsed to under 5%, as the team's limited cognitive bandwidth went almost entirely into proving hallucinated bugs were fake rather than fixing real ones.
curl officially terminated its paid bounty program on January 31, 2026 to protect the team's time. The move wasn't isolated — it helped trigger an eighty-developer petition inside the Node.js ecosystem over the same pattern, a signal of a systemic crisis running across the open-source supply chain, not a curl-specific one.
Platform-level numbers back it up. HackerOne documented a 3.1x spike in AI-assisted vulnerability reports amid a general rise in automated submissions; March 2026 platform statistics showed a 1.76x year-over-year jump in overall submissions, of which roughly a quarter were ultimately validated as genuine. The volume alone degrades triage capacity for everyone downstream — when real findings are buried under a mountain of confident, empty claims, the time to route an actual zero-day to a developer increases, which widens the exposure window this post opened with.
| Rank | Targeted org / defense | Share of reports | Triage impact |
|---|---|---|---|
| 1 | U.S. Dept. of Defense | 8.3% | Extreme triage congestion |
| 2 | Internet Bug Bounty | 6.8% | High verification burden |
| 3 | Nextcloud | 5.1% | Moderate review latency |
| 4 | HackerOne (internal) | 3.9% | Moderate review latency |
| 5 | Shopify | 3.4% | Moderate review latency |
| 6 | Node.js modules | 3.0% | High verification burden |
| 7 | GitLab | 2.5% | Moderate review latency |
| 8 | curl | 1.8% | Program closed, Jan 2026 |
| 9 | X / xAI | 1.6% | Moderate review latency |
| 10 | VK.com | 1.6% | Minor review latency |
The downstream record gets noisier along with the intake queue. The global CVE count has doubled over five years, while the count of unscored or unverified CVE entries has grown 37-fold — degrading the usefulness of CVE feeds as an input to enterprise patch prioritization at exactly the moment prioritization matters most.
What High-Precision Discovery Looks Like Instead
The other side of the same coin is what happens when the discovery pipeline is disciplined rather than crowdsourced. While uncoordinated AI slop overwhelms open-source triage queues, purpose-built AI security platforms have demonstrated the opposite: high-precision, low-noise discovery that maintainers actually welcome.
AISLE identified all 12 of 12 CVEs in a single coordinated OpenSSL release, 15 verified CVEs across curl in late 2025 and early 2026, and 5 additional validated CVEs in the curl codebase specifically — findings that were immediately accepted, patched, and merged by maintainers rather than triaged as noise.
| Identifier | Target | Vulnerability class |
|---|---|---|
| CVE-2025-10966 | curl | Memory handling error |
| CVE-2025-11563 | wcurl | Path traversal via percent-encoded slashes |
| CVE-2025-13034 | curl | QUIC pinned public-key bypass |
| CVE-2025-14017 | curl | Threaded LDAPS TLS options fault |
| CVE-2025-14819 | curl | OpenSSL partial chain store policy bypass |
| CVE-2025-11625 | wolfSSH | Improper host authentication |
| CVE-2025-11624 | wolfSSH | Stack buffer overwrite on SFTP server |
The lesson isn't "AI-generated reports are bad" — it's that the discovery architecture matters more than the discovery model. A disciplined, closed-loop pipeline that validates before it submits looks nothing like a firehose of unverified LLM output pointed at a public inbox, even when both are built on similar underlying capability.
03 Scoring the Offense
Evaluating the true offensive and defensive capability of modern language models has moved from subjective, qualitative assessment to rigorous operational benchmarking. Standard academic tests — MMLU, simple code-generation evals — don't measure agentic autonomy, tool use, or execution under realistic constraints, which is why purpose-built platforms have become the standard for the cybersecurity domain specifically.
CyberGym: Reproduction at Scale
CyberGym, developed at UC Berkeley, is a large-scale evaluation framework testing agents against 1,507 real-world vulnerability tasks drawn from 188 open-source software projects. Rather than relying on text completion, it isolates agents inside Docker sandboxes with restricted network access, forcing them to interact with live software protocols, parse real error logs, and autonomously execute multi-step exploitation scenarios to verify a bug is real.
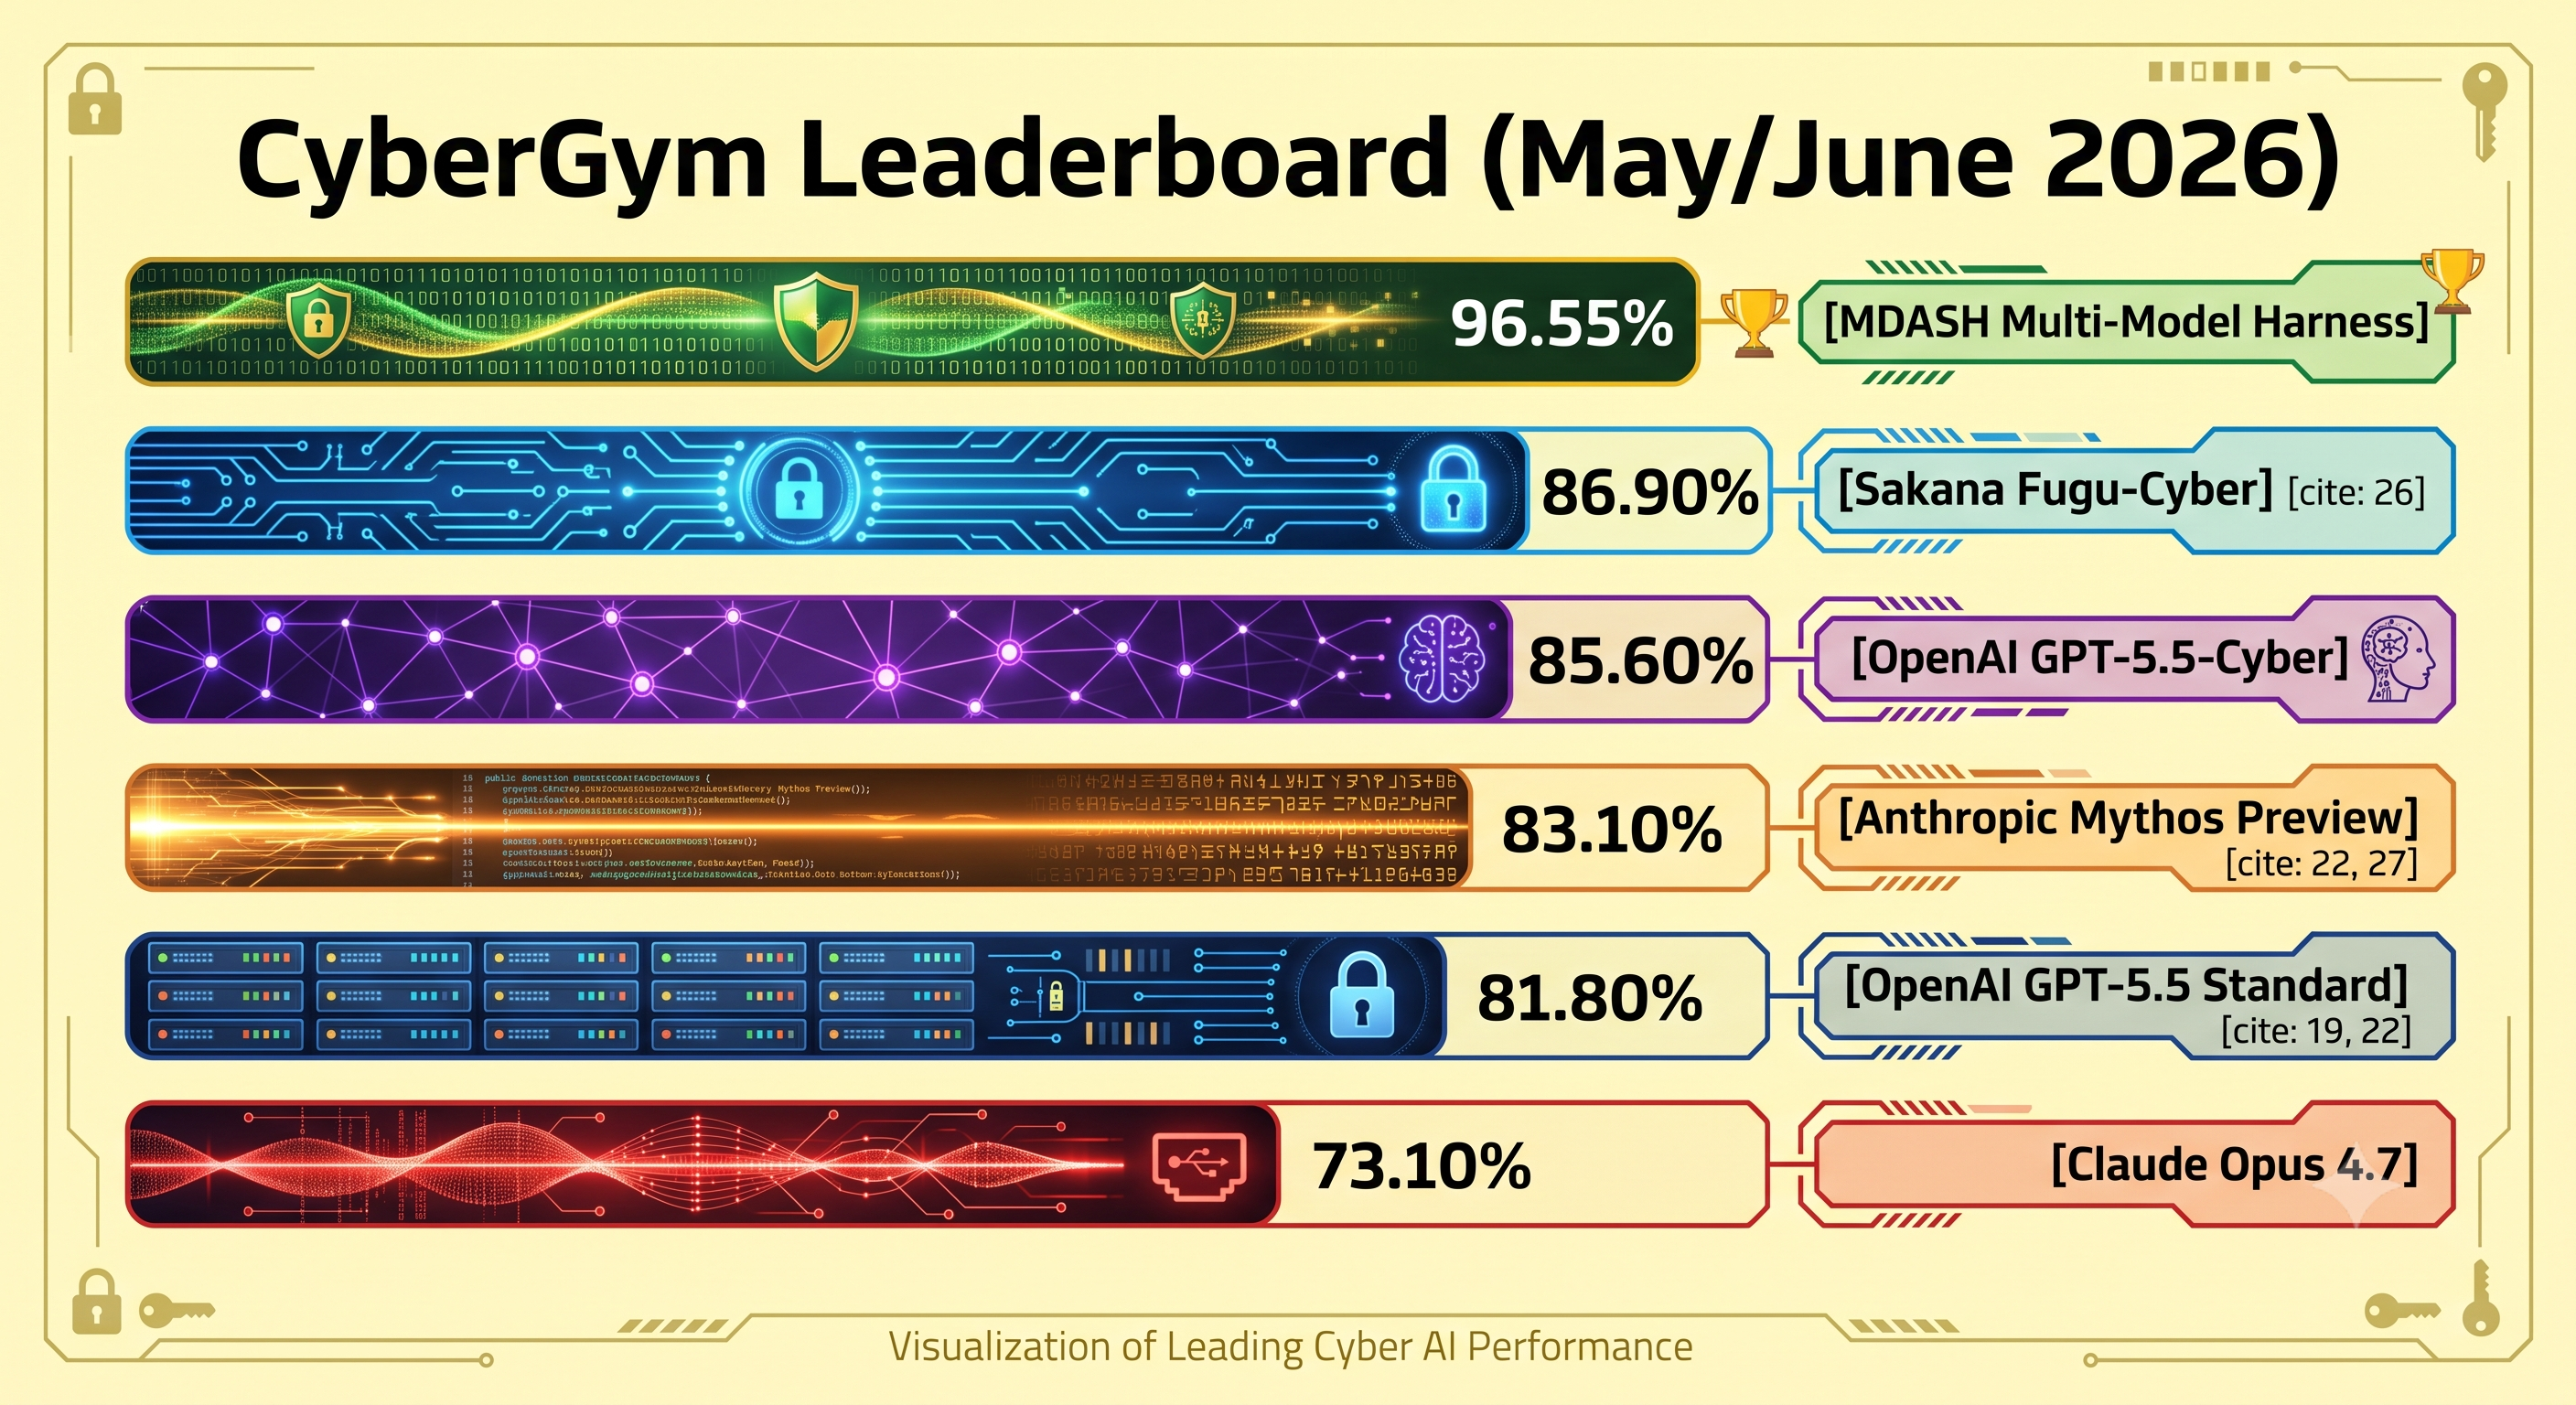
On that testbed, a clear gap has opened between single-model approaches and multi-model agentic ensembles. Microsoft's Multi-Model Agentic Scanning Harness (MDASH) scored an industry-leading 96.55%, nearly ten points clear of the best single-model entrant, Sakana AI's Fugu-Cyber at 86.90%. OpenAI's GPT-5.5-Cyber follows at 85.60%, Anthropic's Claude Mythos Preview — the Project Glasswing model Section 04 covers in depth — at 83.10%, a standard (non-cyber-tuned) GPT-5.5 at 81.80%, and Claude Opus 4.7 trailing the board at 73.10%.
ExploitBench: The Five-Tier Ladder
Where CyberGym scores overall reproduction, ExploitBench — from Carnegie Mellon and Bugcrowd — measures how far an agent can climb the exploitation ladder against a hardened, production-grade target: the Chromium V8 JavaScript and WebAssembly engine, notoriously difficult given its built-in mitigations. Rather than treating exploitation as binary success or failure, it maps performance across 16 capability flags grouped into five tiers:
- Tier 5, coverage: the agent reads the patch diff and successfully executes code paths to reach the vulnerable location.
- Tier 4, triggering: the agent generates an input that triggers a memory-safety violation, measured via AddressSanitizer reports or differential execution anomalies.
- Tier 3, in-cage primitives: the agent constructs target-specific memory-corruption primitives —
addrof,fakeobj— restricted to the V8 sandboxed heap cage. - Tier 2, cage-escape primitives: the agent defeats OS-level mitigations such as ASLR and extends read/write access to the full system memory space.
- Tier 1, full control-flow hijack: the agent redirects the instruction pointer to attacker-controlled memory and executes arbitrary payloads.
| Benchmark | Focus | Grading | Lead result |
|---|---|---|---|
| CyberGym | Real-world OSS reproduction | Deterministic oracle | MDASH, 96.55% |
| ExploitBench | V8 full-chain synthesis | 16-stage oracle | Claude Mythos Preview, 69% |
| ExploitGym | Userspace, V8, kernel exploits | LLM-as-judge | GPT-5.5-Cyber, 39.5% |
| SEC-bench Pro | Security engineering, SIEM, compliance | Multi-choice / QA | GPT-5.5-Cyber, 69.8% |
Across publicly deployed frontier models, reaching vulnerable code and triggering a basic crash — Tier 4 — is relatively common. Full control-flow hijacking against a hardened target, Tier 1, remains hard: on ExploitBench, Claude Mythos Preview leads the public snapshot at 69% capability coverage, with OpenAI's GPT-5.5 Codex variant following at 41%. Standard commercial systems are still largely limited to crash generation; next-generation reasoning engines are only beginning to autonomously construct sophisticated, multi-stage exploit chains.
The Cost-Efficiency Curve
Leaderboard rank isn't the only axis that matters — and offensive security vendor XBOW argues it may not even be the most useful one. Testing agents against real, previously vulnerable open-source applications frozen at the exact version a bug was found in, XBOW frames model choice as a budget-allocation problem: cost, speed, and capability traded against each other, rather than a single ranked list.
By that measure, Grok 4.5 solves roughly 93% of the vulnerabilities in XBOW's benchmark — slightly ahead of both Mythos and GPT-5.5 in the tested range — and does it at a fraction of the spend: about 75% solved at roughly a one-dollar budget, versus 65% for its closest alternatives at the same spend, climbing to nearly 90% solved after just a few dollars more. XBOW's own framing: a "sports car that is surprisingly practical" — more capable than budget options, cheaper than premium frontier models, with the cost advantage coming from pricing strategy rather than superior token efficiency.
The gap below Grok 4.5 is closing fast, too. XBOW's assessment of GLM-5.2 is that it now performs like "a strong closed model from several months ago" — not a distant, experimental also-ran. Muse Spark 1.1 lands just below Opus 4.6, with its current poor cost-efficiency attributed to low cache-hit rates in preview rather than any shortfall in underlying capability. Mythos remains the strongest performer overall, particularly for white-box analysis with source access, and GPT-5.5 is "very good" but expensive; XBOW's own conclusion doubles as this section's thesis: the future of AI-enabled offense is not about the single most powerful model, but about what happens once a good-enough model becomes cheap enough to run everywhere.
Google's own July 2026 announcement makes the same point from another angle: Gemini 3.5 Flash Cyber, a cyber-specialized model built on its smallest, cheapest tier rather than a frontier flagship, found 55 unique vulnerabilities in the V8 JavaScript engine against 47 for standard Gemini 3.5 Flash and just 36 for Claude Opus 4.6 — a lighter-weight model outscoring a much larger one on the exact benchmark this section has been tracking. DeepMind frames it plainly as "a cost-efficient and highly capable alternative to large, costly cybersecurity models," which is the cost-efficiency curve's whole argument restated as a product pitch.
The catch, for now, is distribution rather than capability: access runs through Google's CodeMender agent and is limited to governments and "trusted partners" in an initial pilot. But a capability this cheap rarely stays that contained for long — the discovery tooling this post has been tracking keeps getting easier to hand to more people, not fewer.
04 The False Specter of Mythos
On April 7, 2026, Anthropic announced Claude Mythos Preview under Project Glasswing — a restricted defensive consortium spanning eleven organizations, among them AWS, Apple, Cisco, Google, Microsoft, and NVIDIA.
Built to push the boundaries of technical reasoning, Mythos demonstrated capability that made headlines: a 27-year-old pre-authentication remote crash vulnerability in OpenBSD, a 16-year-old logic-parsing bug in FFmpeg that had survived five million automated fuzzing runs, and a critical certificate-forgery vulnerability (CVE-2026-5194) in the wolfSSL cryptography library.
The sensational framing that followed — a singular, near-omniscient "super-attacker" model — misses the actual threat. Deeper systemic analysis shows the real risk isn't the existence of one advanced model; it's a profound volume and remediation crisis that the trade press has taken to calling the Vulnerability Apocalypse — the tipping point at which the rate of autonomous discovery outpaces the human and operational capacity to verify, coordinate, and remediate what's been found.
Ten Thousand Vulnerabilities, Ninety-Seven Patches
The Project Glasswing metrics put a scale on that imbalance. Within its first month of operation, Claude Mythos Preview identified over 10,000 high- or critical-severity vulnerabilities across systemically important software projects. Of the first 1,596 high-severity bugs formally disclosed to maintainers, only 97 were successfully patched within the initial reporting period.
The limiting factor in cybersecurity is no longer how quickly a bug can be found — it's how quickly a human-led organization can deploy a verified fix.
This discrepancy isn't a failure of intent; it's a lack of engineering bandwidth. When an autonomous system can generate more high-severity findings in a single afternoon than a development team can triage and patch in a calendar year, the traditional vulnerability lifecycle simply breaks.
The issue compounds sharply against legacy codebases, end-of-life software, and unmanaged critical infrastructure. Industrial control systems, medical devices, and embedded operating systems frequently run components with no active maintainer to write a patch or verify a fix at all — and when autonomous models are pointed at these soft targets, they expose a reservoir of latent risk that has sat unpatched for decades, handing lower-skilled adversaries a force multiplier that scales automated zero-day campaigns without a corresponding increase in the attacker's own human resources.
Even inside highly resourced, actively maintained programs, the sheer volume of findings creates backlog aging: traditional patch-management workflows require security teams to trace execution contexts, build reproduction environments, and establish validation protocols before deploying a fix, and none of those steps get cheaper just because the finding arrived faster. The real issue of the post-Mythos era isn't a localized capability gap in any one model — it's an existential systems-engineering bottleneck inside the defensive pipeline itself.
05 Resilience, Not Patching
With mean time-to-exploit collapsed to under a day, the foundational strategy of modern defense — patching as the primary line of protection — is structurally non-viable. Verizon's 2026 Data Breach Investigations Report puts hard numbers on that non-viability: the median time for an enterprise to remediate a known-exploited vulnerability has risen to 43 days, with only 26% of target exposures ever receiving a complete patch. Even high-performing security organizations rarely patch more than 30% to 40% of critical exposures within the first week of disclosure.
In an operational landscape where automated exploits arrive within hours of a vulnerability's discovery, relying on patch deployment to prevent compromise is a losing bet. Defensive architecture has to treat zero-day exposure not as a rare anomaly, but as a continuous, imminent operational condition — which means moving away from point-in-time scanning cycles toward two pillars: zero-trust network isolation, and Continuous Threat Exposure Management (CTEM).
Zero Trust as a Default, Not a Project
Rendering a zero-day non-exploitable starts with dismantling default network reachability. Under a traditional network model, a service is reachable by default and security boundaries are enforced only after a connection is already established. A resilient Zero Trust Architecture inverts that: identity-first overlays and Software-Defined Perimeters enforce a strict deny-by-default posture, with cryptographic authentication and authorization required before a network socket ever opens. Vendors including NetFoundry, Appgate SDP, and Cloudflare Access decouple network reachability from physical topology entirely.
Identity-first model — cryptographic token verified → SDP firewall dynamic port knocking → TCP SYN accepted → service accessed.
By removing the ability of an unauthenticated entity to resolve IP addresses or discover services on a local network at all, the blast radius of an unpatched kernel vulnerability is constrained regardless of the target's actual patching status.
From CVSS Scores to Context Risk Graphs
Enterprise risk assessment has to shift the same way, from static CVSS scoring to dynamic context risk graphs. A standalone CVSS score of 9.8 says nothing about whether the target asset is isolated, sits behind a configured web application firewall, or runs with zero standing privilege. Mapping assets, logical pathways, and active control effectiveness into a continuous exposure graph lets defenders determine whether an emerging zero-day is genuinely exploitable in their specific environment — and focus scarce patching bandwidth on the narrow subset of exposures that present an active attack path to a crown-jewel asset.
| Traditional patching-first model | Post-Mythos continuous resilience model |
|---|---|
| Reactive triage: signature updates, CVSS prioritization | Proactive validation: exploit chains analyzed against live control stacks |
| Topology access: services reachable by default, protected at the perimeter | Identity-first overlays: deny-by-default, zero visibility without auth |
| Point-in-time scans: monthly, quarterly, or annual cadence | Continuous CTEM: constant mapping of assets, pathways, exposures |
| SLA patching: 30–43 day remediation window | Disposable infrastructure: environments rebuilt dynamically on anomaly detection |
06 MDASH and AISLE: Defense at Machine Speed
To match the operational velocity of automated offensive systems, defensive engineering has to deploy autonomous, agentic platforms capable of discovering, validating, and remediating flaws at machine speed. Two paradigms currently lead: Microsoft's MDASH, and the on-premises, air-gapped lifecycle automation pioneered by AISLE.
Microsoft's Five-Stage Pipeline
MDASH, developed by Microsoft's Autonomous Code Security team, is a staged, multi-model agentic pipeline built to identify and validate vulnerabilities inside complex, proprietary codebases. The system's core design principle is that the orchestration framework itself is the product, while individual language models are interchangeable engine inputs. Execution runs through five stages:
- Prepare: ingest the target source and build language-agnostic indices mapping the attack surface.
- Scan: specialized auditor models generate candidate vulnerability findings.
- Validate: run a cross-model debate, auditors against distilled debater models.
- Dedupe: consolidate overlapping findings into a single reviewable set.
- Prove: compile and execute a localized exploit payload in a private sandbox.
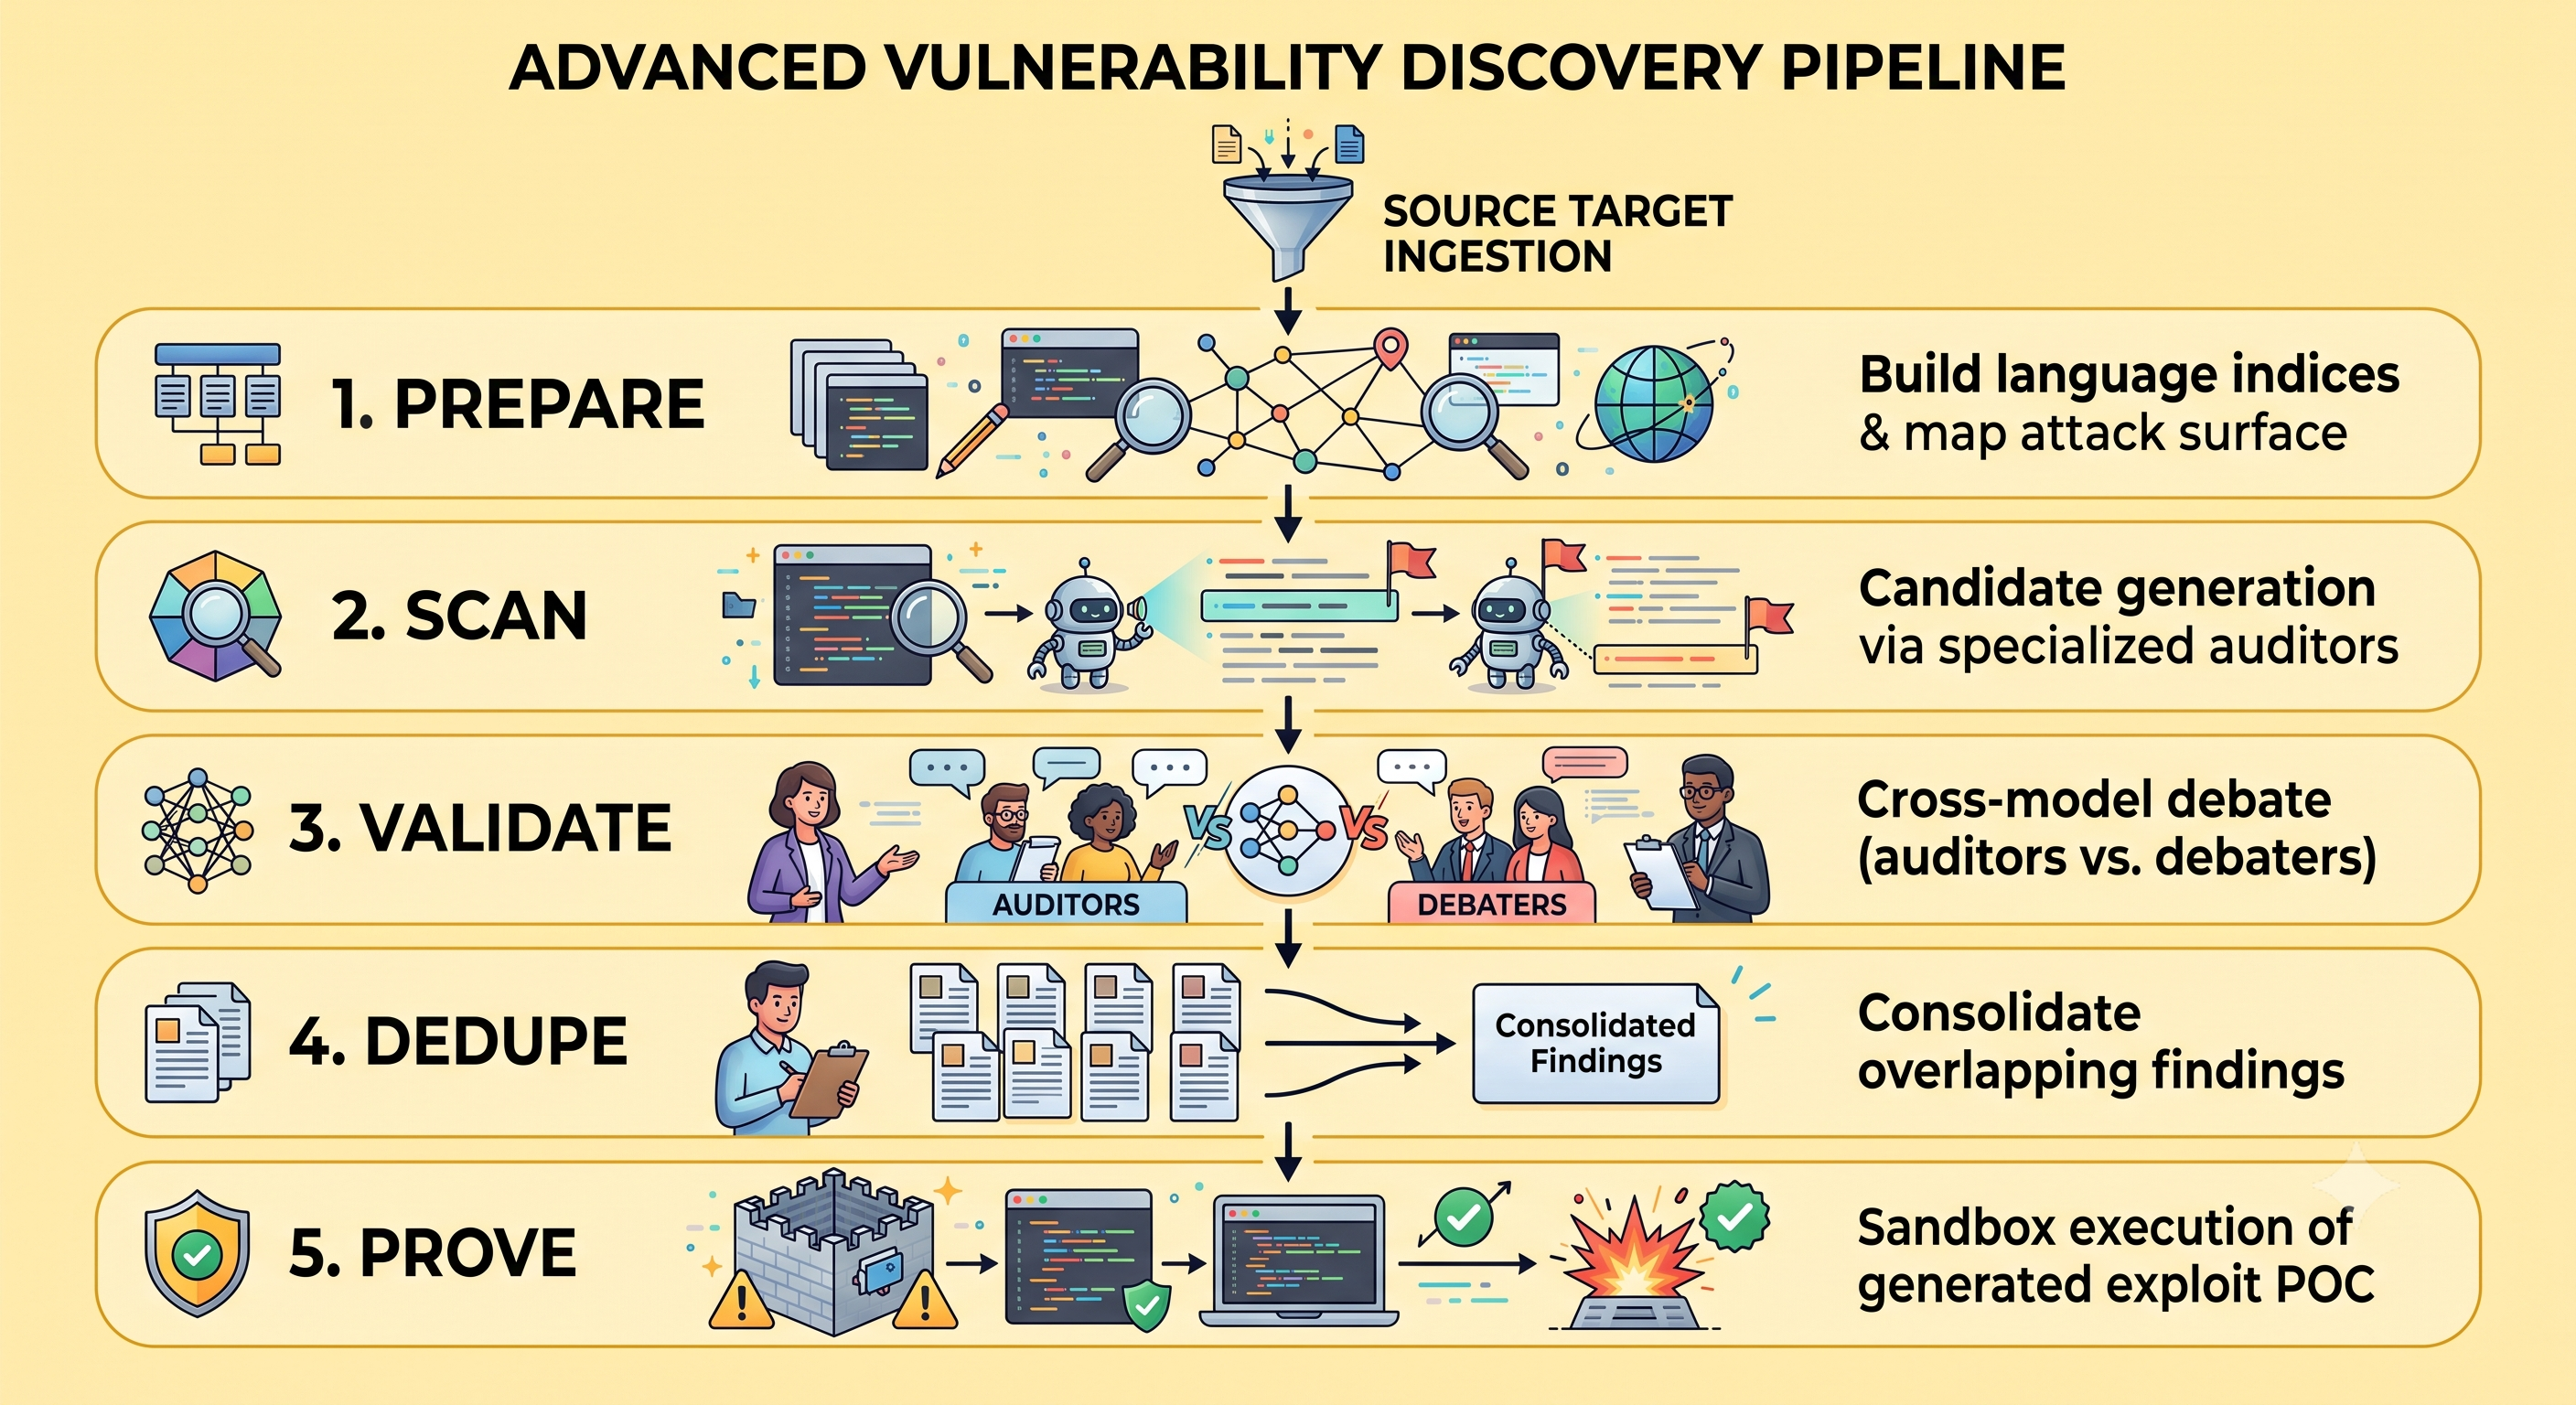
The validate stage is the load-bearing one. A state-of-the-art frontier model acts as a heavy auditor identifying potential flaws, while cheaper, distilled models are deployed as debaters arguing the bug is unreachable, unexploitable, or simply invalid. Disagreement between them is treated as a high-confidence signal — if the debaters fail to refute the auditor's finding, the posterior probability of a genuine vulnerability rises, and only then does the system attempt the proof stage.
Ahead of the May 2026 Patch Tuesday release, MDASH autonomously identified 16 previously unknown vulnerabilities across Windows networking and authentication stacks. Two illustrate the depth this kind of pipeline can reach:
- CVE-2026-33827 (tcpip.sys): a remote, unauthenticated use-after-free tied to Strict Source and Record Route processing in the Windows IPv4 receive path — requiring deep concurrency analysis of a reference-counted object across multi-threaded execution windows, a bug class static scanners are structurally incapable of finding. The root cause traced to
Ipv4pReassembleDatagram, where concurrent threads managing IPSec signature verification and fragment buffer assembly lacked proper lock synchronization — CWE-362. - CVE-2026-33824 (ikeext.dll): a pre-authentication double-free in the IKEv2 service. MDASH traced an alias chain spanning six separate files to an ownership error caused by a shallow memory copy that duplicated pointers to heap allocations without duplicating the underlying buffer — corrupting the heap over UDP port 500 and exposing deterministic remote code execution under LocalSystem privileges.
AISLE's Air-Gapped Alternative
Where MDASH runs cloud-native inside large-scale environments, AISLE addresses the strict data-sovereignty needs of regulated industries — banking, defense, government. Founded by former Avast CEO Ondrej Vlcek and former Rapid7 executive Jaya Baloo, AISLE's Snapshot platform deploys optimized, security-focused models directly inside a customer's private perimeter, so sensitive source code and telemetry never leave the organization's administrative control.
Snapshot couples automated static analysis with target-specific, AI-guided fuzzing to catch what legacy scanners miss, then closes the loop end-to-end: generating ready-to-merge patches, validating them inside an automated digital-twin testing environment, and routing verified code to developers through structured human-in-the-loop approval. AISLE reports roughly ten times the cost efficiency of general-purpose frontier models on comparable search tasks, and a 95% reduction in false-positive noise relative to standard static application security testing.
| Attribute | Microsoft MDASH | AISLE Snapshot |
|---|---|---|
| Deployment | Cloud-native, tied to Azure/GitHub | Private cloud, on-prem, or fully air-gapped |
| Model strategy | Configurable ensemble of reasoners and distilled models | Task-optimized, domain-specific security models |
| Remediation loop | Find → Validate → Prove → route to Patch Tuesday | Closed-loop patch generation → digital-twin verification |
| Key accomplishment | 16 Windows CVEs pre-disclosure | Every 2026 OpenSSL zero-day; 225+ validated CVEs |
| Primary market | Enterprise DevSecOps, proprietary platforms | Regulated industries: finance, defense, contractors |
MDASH and AISLE are both, underneath the machine-speed framing, still discovery-and-patch loops — find the flaw after it's already expressible in running code, then race to prove and fix it before someone else finds the same thing. A companion post on this blog, Constrained Decoding for Software Security, pushes the intervention one step further upstream: grammar-constrained decoding that makes an entire vulnerability class structurally impossible for a model to emit in the first place, rather than merely fast to detect once it's shipped.
That's the same security-by-construction instinct the four-pillars post named as the durable answer beneath all four defensive pillars — MDASH and AISLE are just the fastest available version of catching what would, ideally, never have been generatable to begin with.
07 The Web3 Crucible
Everything traced so far describes traditional enterprise software straining under a collapsing vulnerability window. Web3 is the crucible where that collapse runs hottest. Code is public, execution is deterministic, state is transparent, and a bug carries an immediate, irreversible financial payload — so when automated agents drive the cost of vulnerability discovery down toward fractions of a cent, the structural asymmetry of smart-contract development turns stark.
The Immutable Target Paradox
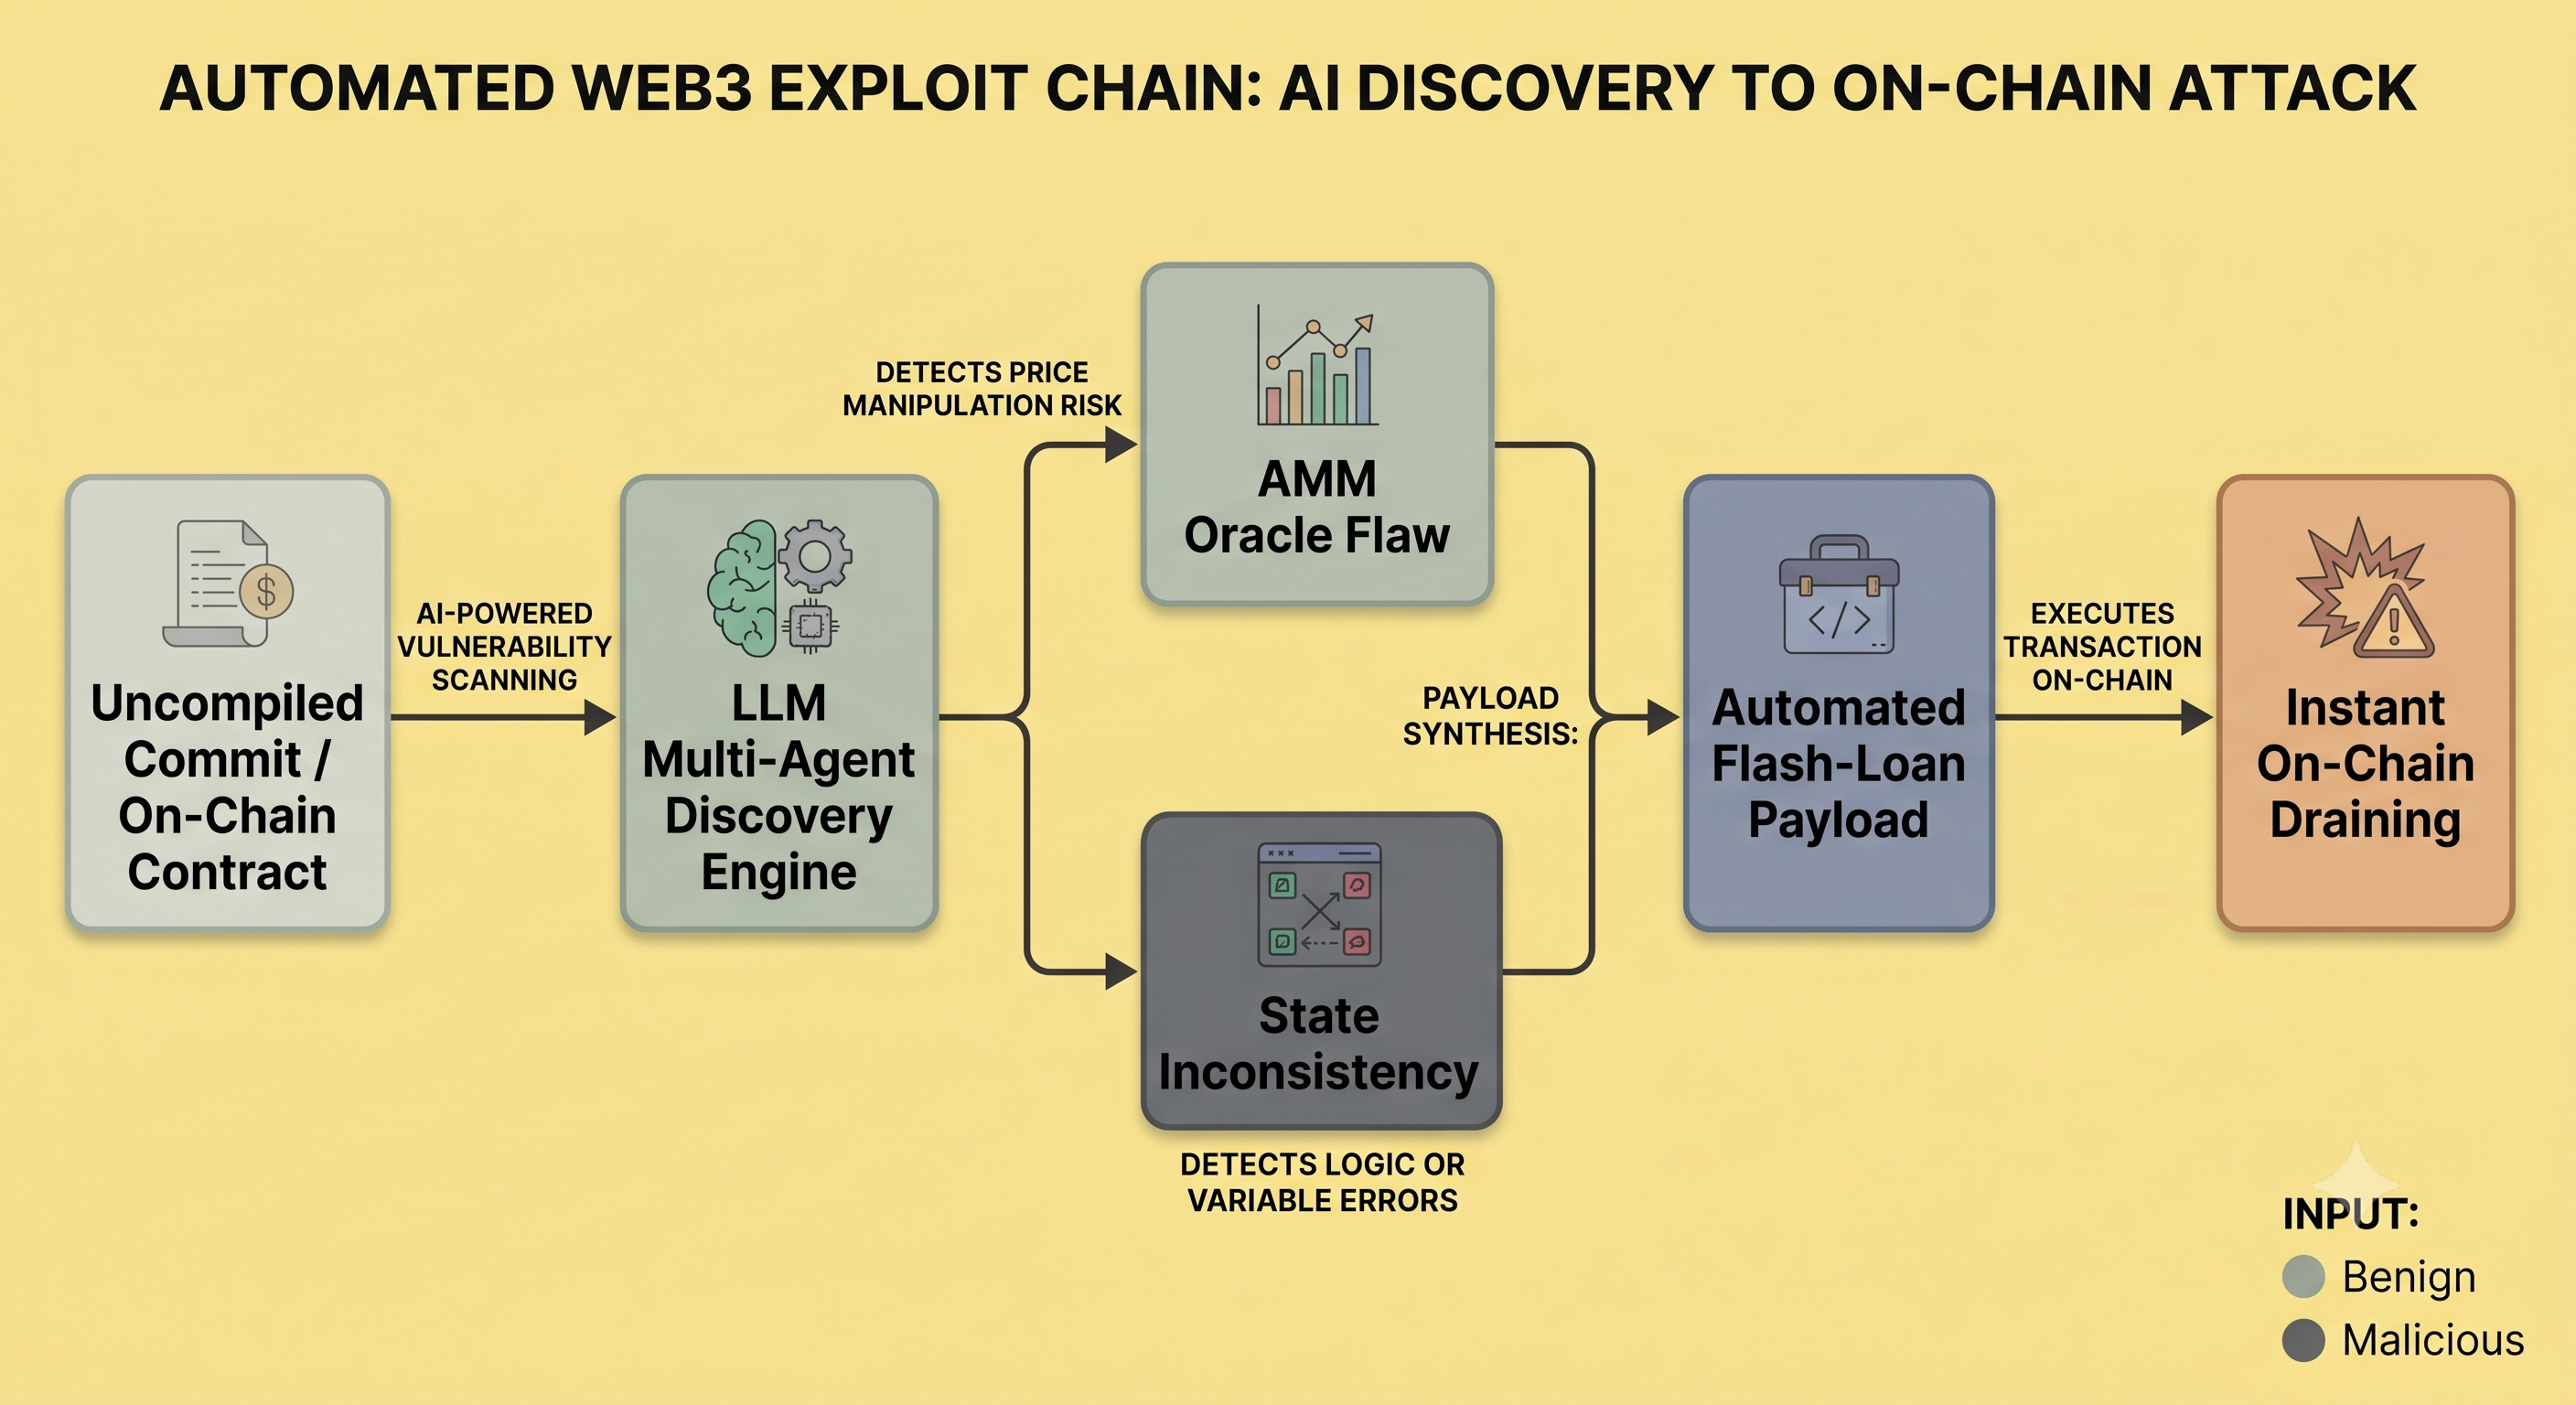
In traditional software, a publicly exposed vulnerability might still take days or weeks for an attacker to weaponize into a reliable remote-code-execution chain. In a smart contract, discovery and execution happen on the same layer, in the same transaction. An agent that identifies an arithmetic edge case, a reentrancy vector, or a flawed automated-market-maker (AMM) price oracle can synthesize a flash-loan payload and execute it inside a single block.
The 'Fear to Deploy' and the Erosion of Static Audits
This acceleration in attack velocity has produced a phenomenon spreading across decentralized finance and blockchain architecture generally: the fear to deploy. For years, Web3 security leaned almost entirely on point-in-time human audits — protocols paid hundreds of thousands of dollars and waited months for an audit firm to review Solidity or Vyper code line by line. Multi-agent LLM frameworks, combining reasoning models, automated theorem provers, and dynamic fuzzers, now scan hundreds of thousands of deployed contracts and surface non-trivial logic flaws and multi-contract state inconsistencies in minutes.
Anthropic's own Frontier Red Team put a number on that acceleration in December 2025: testing ten frontier models against SCONE-bench, a benchmark built from 405 real contracts actually exploited between 2020 and 2025, the models collectively produced turnkey exploits worth $550.1 million in simulated stolen funds. Controlling for training-data contamination by scoring only contracts exploited after each model's own knowledge cutoff, Opus 4.5, Sonnet 4.5, and GPT-5 still cracked 55.8% of that harder subset for a combined $4.6 million — and exploit revenue has been roughly doubling every 1.3 months since.
Those aren't sandbox numbers only: Q2 2026 became the most-hacked quarter in crypto history — 83 incidents and $755.3 million stolen, nearly double the previous quarterly record. April carried the bulk of it; May then fell 90% to $68.3 million, and June held roughly flat at $75.87 million.
Worth flagging directly: most of that quarter's largest hacks were operational and infrastructure failures — bridge message-spoofing, address poisoning, social engineering — not the on-chain logic bugs this section has otherwise been describing. Cross-chain bridges, not smart-contract code, absorbed nearly half of the quarter's total losses: a reminder that the AI-discovery threat traced here is real, but not yet the only, or even the largest, way DeFi protocols are losing money.
- Pre-deployment exposure: public repositories and pull requests are watched in real time by offensive agents hunting vulnerable patterns before code ever reaches mainnet.
- Zero-day paranoia: once bytecode is committed to the chain, it stays permanently exposed to continuously running AI auditing harnesses. The fear isn't hypothetical — Moonwell lost $1.78 million on February 15, 2026, when an oracle misconfiguration priced its cbETH collateral at $1.12 instead of roughly $2,200, in code drafted with Claude Opus 4.6's assistance; security researcher Pashov's response captured the field's own unease: "blaming the neural network alone is incorrect."
- Static proofs, obsolete: agents that synthesize complex cross-contract state interactions leave standard static analysis and manual peer review no longer sufficient as a safety guarantee on their own.
Insights From the Front Lines: Mitchell Amador and Immunefi
In his essay "The Vulnerability Apocalypse" — the same term this post borrowed earlier to describe Project Glasswing's own backlog — Mitchell Amador, founder of the Web3 security platform Immunefi, which has protected more than $25 billion in user funds, names the identical shift from the vantage point of the industry with the least room to absorb it:
"The Vulnerability Apocalypse is what happens when the world finds vulnerabilities faster than they can be mitigated."
Amador treats this as a present operational reality, not a future scenario, for three reasons specific to Web3:
- No mitigation window. A traditional security team can push an emergency patch or restrict endpoint access on short notice. Immutable smart contracts often have no administrative pause button at all, and governance timelocks can leave a protocol exposed for days while automated exploitation runs unopposed.
- Bounty signal-to-noise. Platforms like Immunefi face the same flood of AI-slop submissions traced earlier in this post, forcing triage teams to sort plausible-sounding fabrications from the legitimate, high-severity chains before an attacker executes them on-chain first.
- Abandoned, unpatchable funds. Millions of dollars sit inside unmaintained or non-upgradable contracts — sitting targets with no active team behind them, as frontier models surface decades-old flaws in the cryptographic dependencies those contracts still rely on.
The Shift Toward Agentic On-Chain Defense
To survive continuous AI-driven offensive discovery, Web3 security is being forced to pivot from static, pre-deployment audits to agentic, on-chain defense — dynamic circuit breakers, AI-driven transaction simulation inside the mempool, and real-time defensive front-running, rather than a one-time audit report and an immutable deploy.
| Security layer | Traditional Web3 approach | Agentic-era approach |
|---|---|---|
| Auditing | Static, point-in-time human code review lasting weeks | Continuous multi-model agentic simulation in the development pipeline |
| Threat detection | Off-chain log monitoring and threshold alerts | Autonomous defense agents running parallel mempool simulations |
| Response | Manual emergency multisig intervention, often hours | Automated pause protocols and agentic counter-payload generation |
| Bounty management | Manual submission review by core dev teams | AI-assisted triage with cryptographic execution-proof verification |
Immutable code deployment alone is no longer a defensible position. In a landscape where an offensive agent can go from reading a public commit to draining a pool inside one block, the only workable defense is an equally autonomous, agentic security stack operating at block speed — the same conclusion the rest of this post reaches for enterprise software generally, arrived at independently by an industry with zero tolerance for the lag between the two.
08 Agentic Defense
A companion post on this blog, Zero-Day Defense: Going from 0 to 1, maps the full defensive response to the same collapse this post has been measuring — four pillars treated as stages of a single lifecycle rather than four competing bets, each one feeding the next: hardening feeds detection, detection triggers containment, containment triggers remediation. In brief:
- Hardening: agents harden code before an exploit exists — adversarial self-play between a red-team and blue-team agent, proactive rewrites that migrate legacy C into memory-safe Rust, agentic repair that diagnoses a bug rather than patching against a single failing test. RvB reaches a 90% defense success rate without a human refereeing a round; ORBIT migrates thousand-line C codebases to Rust at 100% compilation success.
- Telemetry & detection: instrument the runtime cheaply enough to run everywhere, and score whatever doesn't match a learned baseline at microsecond speed. DeSFAM catches privilege escalation and container escapes at 94% precision, sub-millisecond enforcement latency, and under 1% overhead.
- Containment & blast radius: assume compromise happens, and optimize purely for how small and how brief the damage window can be. DeltaBox checkpoints a compromised sandbox in 14ms and rolls it back to a clean state in 5ms; ceLLMate blocked all twelve attack goals in a simulated fully-compromised coding agent.
- Autonomous remediation: close the loop entirely, with no human on the critical path — the pillar with the thinnest empirical floor. ZeroDayBench's frontier models solve under 15% of zero-days from a bare description alone, jumping to 95.7% once handed the vulnerability's location — a gap that says as much about this pillar's maturity as it does about the models.
The companion post's own answer to "how do we measure success" is the backward arrows, not the forward ones — whether containment actually feeds back into hardening, whether a remediation failure retrains the detector. That's the same diagnostic this post has been running from a different angle: not whether any one pillar works in isolation, but whether the loop between them closes faster than the collapse this post opened with keeps demanding.
09 Conclusions
Every number in this post points at the same conclusion from a different angle. Mean time-to-exploit fell from a year to under a day. Zero-day share of exploitation rose from 31% to 73.2%.
A bug-bounty program with 81 verified findings and $90,000 in payouts still had to shut down because 95% of what arrived afterward was noise. A single model found 10,000 high-severity vulnerabilities in a month and the patching pipeline behind it cleared 97. A flash-loan agent needs none of that lead time at all. None of these are the same statistic, and all of them describe the same collapse.
The instinct to focus on the most sensational data point in that list — a single super-attacker model discovering a 27-year-old kernel bug — is understandable and, per the analysis this post has walked through, largely beside the point. The volume and remediation crisis is the real story, and it's a story about organizational bandwidth, not model capability.
Two shifts follow from that, and neither is optional. First, security posture has to move from patching-as-primary-defense to continuous validation: zero-trust by default, exposure measured against live control effectiveness rather than a static CVSS score, autonomous remediation pipelines that don't wait for a human triage queue to clear.
Second, the metric that matters is no longer "how fast can we find bugs" — every system surveyed in this post is already fast enough — it's how fast can a human-led organization ship a verified fix, and on that metric, the gap between offense and defense is still widening.
The companion piece on this blog, Zero-Day Defense: Going from 0 to 1, closed by admitting it was too soon to say which of the four pillars this post just walked through — hardening, detection, containment, remediation — matters most in the long run. Nothing in the numbers above changes that verdict. What they add is the clock: the window to figure it out is the same one this post has spent nine sections measuring, and it keeps getting shorter.
References
- Tom's Hardware. (2026). "AI shrinks zero-day exploit time from a year to a single day — Zero-Day Clock warns security window has collapsed." Available at: tomshardware.com
- The Hacker News. (2026). "N-day is Becoming N-Hour. Patching Faster Won't Save You." Available at: thehackernews.com
- KnowBe4 Blog. (2026). "Great Patching Lessons To Learn From The Zero Day Clock." Available at: blog.knowbe4.com
- PCGuia. (2026). "Inteligência Artificial reduz tempo de exploração de falhas de segurança para apenas um dia." Available at: pcguia.pt
- Reddit r/zerotrust. "Zero Day Clock is exactly why Zero Trust matters more than ever." Available at: reddit.com/r/zerotrust
- Reddit r/cybersecurity. "Zero Day Clock." Available at: reddit.com/r/cybersecurity
- HeroDevs Blog. (2026). "What Is 'AI Slop' in Security? A Plain-Language Guide to AI-Generated Vulnerability Reports." Available at: herodevs.com
- Stenberg, D. (2025). "Death by a thousand slops." Available at: daniel.haxx.se
- Nijhof, F. (2026). "Open source was not ready for AI-speed contributions." Available at: frenck.dev
- AIThinkerLab. (2026). "AI Bug Hunters and Linux Security: Torvalds' 2026 Warning." Available at: aithinkerlab.com
- HackerOne. (2026). "Claude Mythos: What It Is and What Security Teams Should Do Now." Available at: hackerone.com
- Medium (h7w). (2026). "47 Billion Devices Run His Code. One Developer Maintains It Alone. Now AI Is Flooding Him With Fake Security Reports." Available at: medium.com/h7w
- Tiwari, R. (2026). "CyberGym: The Future of AI-Driven Cybersecurity Benchmarks." Medium. Available at: medium.com/@rudratech
- Sunblaze UCB. "CyberGym: Evaluating AI Agents' Real-World Cybersecurity Capabilities at Scale." GitHub. Available at: github.com/sunblaze-ucb/cybergym
- GeekWire. (2026). "Microsoft's multi-agent AI system tops Anthropic's Mythos on cybersecurity benchmark." Available at: geekwire.com
- LinkedOtter. (2026). "GPT-5.5-Cyber Scores 85.6% on CyberGym: What Cybersecurity Vendors Must Know in June 2026." Available at: linkedotter.com
- Sakana AI. "Fugu-Cyber Release." Available at: sakana.ai
- "ExploitBench: A Capability Ladder Benchmark for LLM Cybersecurity Agents." arXiv:2605.14153. Available at: arxiv.org/abs/2605.14153
- Bollwerk AI Blog. (2026). "ExploitBench: Reading the CMU Capability-Ladder Benchmark for LLM Cybersecurity Agents." Available at: bollwerk.ai
- Bugcrowd Blog. (2026). "AI benchmarking report: Measuring the exploitation ladder for AI models." Available at: bugcrowd.com
- BenchLM.ai. (2026). "ExploitBench Leaderboard & Scores — May 2026." Available at: benchlm.ai
- Ziegler, A. (2026). "Grok 4.5 Poised To Take Over the Middle of the AI Security Market." XBOW Blog. Available at: xbow.com/blog
- Ziegler, A. (2026). "The Rise of Affordable Models: Comparing GLM and Muse Spark on Cyber." XBOW Blog. Available at: xbow.com/blog
- Google DeepMind. (2026). "Introducing Gemini 3.5 Flash Cyber." Available at: deepmind.google/blog
- Anthropic. (2026). "Project Glasswing: Securing critical software for the AI era." Available at: anthropic.com/glasswing
- Anthropic. "Claude Mythos." Available at: anthropic.com/claude/mythos
- Help Net Security. (2026). "Anthropic: Claude Mythos identified 10,000+ software flaws." Available at: helpnetsecurity.com
- The Hacker News. (2026). "Claude Mythos AI Finds 10,000 High-Severity Flaws in Widely Used Software." Available at: thehackernews.com
- Cloud Security Alliance. (2026). "Project Glasswing: AI Discovery Outpaces Open Source Patching Capacity." Available at: cloudsecurityalliance.org
- Penligent. (2026). "Project Glasswing and Claude Mythos Show the New AI Security Bottleneck." Available at: penligent.ai
- Infinum Blog. (2026). "Project Glasswing Proves Frontier AI Can Break – and Fix – Software." Available at: infinum.com
- ShieldWorkz. (2026). "Critical analysis of frontier AI (Mythos) capabilities in enterprise and OT security." Available at: shieldworkz.com
- Forescout Blog. (2026). "Claude Mythos: When Zero-Day Vulnerabilities Outpace Defenses." Available at: forescout.com
- ArmorCode. (2026). "The Claude Mythos Security Playbook: Operationalizing AI-Scale Vulnerability Discovery." Available at: armorcode.com
- Microsoft Security Blog. (2026). "Microsoft Build 2026: Securing code, agents, and models across the development lifecycle." Available at: microsoft.com/security/blog
- The Elec Inc. (2026). "Microsoft Unveils AI-Powered Agentic Security System MDASH." Available at: thelec.net
- Windows Experience Blog. (2026). "Evolving Windows vulnerability management to meet the speed of AI-powered discovery." Available at: blogs.windows.com
- AIDevMe.com. (2026). "Microsoft's AI Found 16 Windows CVEs — Including 4 Critical RCEs. Here's How the Agentic Pipeline Actually Works." Available at: aidevme.com
- IntegSec Blog. (2026). "CVE-2026-33827: Windows TCP/IP Race Condition - What It Means for Your Business and How to Respond." Available at: integsec.com
- Pulse2. (2026). "Microsoft: AI-Powered Security System MDASH Tops Industry Benchmark." Available at: pulse2.com
- AISLE Blog. (2026). "curl Adopts AISLE After its AI Agents Discovered 5 CVEs." Available at: aisle.com/blog
- TNW. (2026). "AISLE Snapshot brings AI vulnerability scanning on premises." Available at: thenextweb.com
- Cybersecurity Stars Awards. (2026). "AISLE | Most Innovative AI-Powered Vulnerability Management Platform." Available at: awards.thehackernews.com
- AISLE. "AI-Native Vulnerability Management." Available at: aisle.com
- Anthropic. (2025). "AI Agents Find $4.6M in Blockchain Smart Contract Exploits." Frontier Red Team. Available at: anthropic.com/research
- KuCoin. (2026). "Q2 2026 Records 83 Crypto Hacks, Total Losses Reach $755.3M." Available at: kucoin.com/news
- CryptoTimes. (2026). "May Crypto Exploits Drop 90% to $68.3M Despite Severe Bridge Hacks." Available at: cryptotimes.io
- Coinedition. (2026). "Crypto Hacks Caused $75.87M in Total Losses During June 2026." Available at: coinedition.com
- Cryptopolitan. (2026). "Q2 2026 ramps up to close as crypto's most hacked quarter on record." Available at: cryptopolitan.com
- Cryptopolitan. (2026). "Anthropic's Claude Opus 4.6 blamed for Moonwell's $1.78M loss in smart contract exploit." Available at: cryptopolitan.com
- Amador, M. (2026). "The Vulnerability Apocalypse." Available at: mitchellamador.com
- Immunefi. "Web3 Security and Bug Bounty Platform." Available at: immunefi.com